Adaptive game experimentation
Summary
Reinforcement learning for an A/B testing platform.
A game team needed to explore interacting parameters while campaign goals and product conditions changed.
A system that pre-trains on historical data, runs smaller campaigns, learns from results and iterates against product-owner goals.
Tech Stack
- Firebase
- OpenAI Gym
- Python
- TensorFlow
Project workstreams
- 01
1 Week
Solution Architecture Design
Solution Architect - 02
2 Weeks
Hypothesis Generation & Validation
Deep Learning Researcher - 03
4 Weeks
RL Environment Development
Data Engineer,Deep Learning Engineer,Deep Learning Researcher - 04
2 Weeks
RL Algorithms Development
Deep Learning Researcher - 05
6 Weeks
Training & Tuning Cycle pt.1
Deep Learning Researcher - 06
2 Weeks
Data Labelling & Processing & Integration into RL Environment
Data Engineer - 07
2 Weeks
Training & Tuning Cycle pt.2
Deep Learning Researcher - 08
2 Weeks
Integration & A/B Testing & Deployment
Backend Developer,Dev Ops
Tech Challenge
- When tested product goes through various stages of its life-cycle, goals might swap priorities.
- Most of the tests are created manually and managed by humans, with only few parameters changed at once not to introduce over-complexity into results’ interpretation.
- Different parameters, competing goals, lots of statistical events are the factors that introduce additional complexity and need automatic insights extraction.
- Finding complex interaction between the entire list of A/B parameters and real-world state is extremely technically challenging.
Solution
- Our team used recently introduced techniques from reinforcement and deep learning to model complex parameters interaction, time dependent external state and A/B campaign events stream.
- As a result, we have developed a self-learning solution which, firstly, pre-trains itself using historical data and then takes control over the campaigns. Product owner remains in control of goals and parameters.
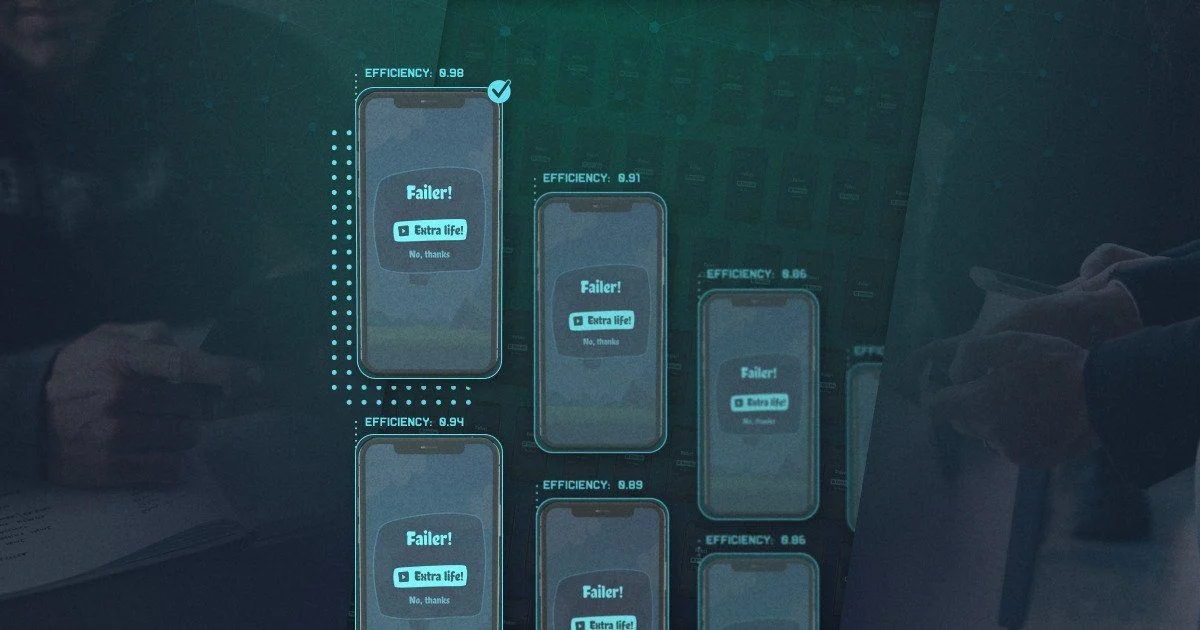
- System creates hundreds of micro-campaigns with different goals and fast-checks hypotheses on a user base sample. Then, it explores the resulting space with deeper tests to maximize the outcomes in each cycle.
- Campaign results are integrated back via learning process and checked against updated goals; the cycle repeats.
- AI explores sophisticated dependencies in parameters/state spaces and their relations with the list of goals, provides opportunities beyond conventional approach to A/B testing, while the rest is controlled by product owner in an intuitive way.
Impact
The approach was tested on a mobile game and compared with a Bayesian optimisation baseline.
Published