Introduction
The power of a well-crafted prompt is often understated. It's an art and science that dictates the quality of the model response. This post explores various techniques and tools for effective prompting to unlock the full potential of the large language models.
WHAT IS A PROMPT?
A prompt in LLM is an input or set of instructions to the model, acting as a question or command to guide the information processing, decision-making, or content generating. The effectiveness of such generative models largely depends on the quality and structure of these prompts.
WHAT IS PROMPT ENGINEERING?
Prompt engineering is the process of creating effective prompts to improve the performance and accuracy of large language models. It involves understanding LLM information processing and crafting prompts that maximize its capabilities, focusing on their structure, language, and alignment with user intent.
Zero-Shot Prompting
ZERO-SHOT PROMPTING
Zero-Shot Prompting enables LLM to perform tasks without specific prior training, relying instead on their understanding from broad initial training. This approach leverages the model's pre-training, which typically involves processing vast amounts of information across numerous topics and formats. As a result, the model has a general understanding and can apply this broad knowledge to new and unseen tasks.
In zero-shot prompting, the model uses its inherent capabilities to infer the task's requirements and generate appropriate responses, demonstrating its ability to generalize and apply learned concepts in novel situations. This method is particularly valuable in scenarios where it's impractical to train a model for every possible task or where the range of potential tasks is too broad to anticipate fully.
Here is one of the examples using the Zero-Shot Prompting technique:
(🤓) ↦ Translate the following English sentence into French: 'Hello, how are you today?'
(🤖) ↦ Bonjour, comment vas-tu aujourd'hui?
Few-Shot Prompting
FEW-SHOT PROMPTING
Few-Shot Prompting is a technique where the model is guided to perform specific tasks by providing a small number of examples, or "shots". This approach stands in contrast to traditional machine learning models that typically require extensive datasets for training on a particular task. In few-shot learning, the examples serve as a context or a template, helping the LLM to understand the desired output format or the type of reasoning required for the task at hand.
The key advantage of few-shot prompting is that it leverages the LLM's broad foundational training on diverse datasets, allowing it to quickly adapt to new tasks with just a few relevant examples. This is particularly useful when gathering a large dataset is impractical or impossible. For instance, if a specific task is too niche or if data is scarce or sensitive, few-shot prompting can still enable effective performance.
Let's illustrate the technique with a classifying example of the sentiment of customer reviews as either positive, neutral, or negative:
(🤓) ↦
Review: 'I love this product, it's amazing!.' Sentiment: Positive
Review: 'This product is okay, but it has some issues.' Sentiment: Neutral
Review: 'I'm disappointed with this product, it didn't meet my expectations.' Sentiment: Negative
Review: 'The features are great, but it's too expensive.' Sentiment: ?
(🤖) ↦ For the provided review, 'The features are great, but it's too expensive.', sentiment can be classified as Neutral.
Chain-Of-Thought Prompting
CHAIN-OF-THOUGHT PROMPTING
The Chain-of-Thought Prompting technique involves structuring prompts to encourage the model to follow and articulate a step-by-step reasoning process, much like how a human might logically break down a problem. Unlike direct-answer methods, where the model provides immediate answers, chain-of-thought prompting aims to make the LLM's thought process visible and explicit.
In practice, this approach involves providing a prompt that not only asks a question but also encourages the model to show its work, so to speak. For instance, in solving a math problem, the model would detail each step in the calculation. For a more nuanced problem, like interpreting a text or planning an event, the model would lay out its understanding of the situation, consider various factors, weigh options, and then arrive at a conclusion.
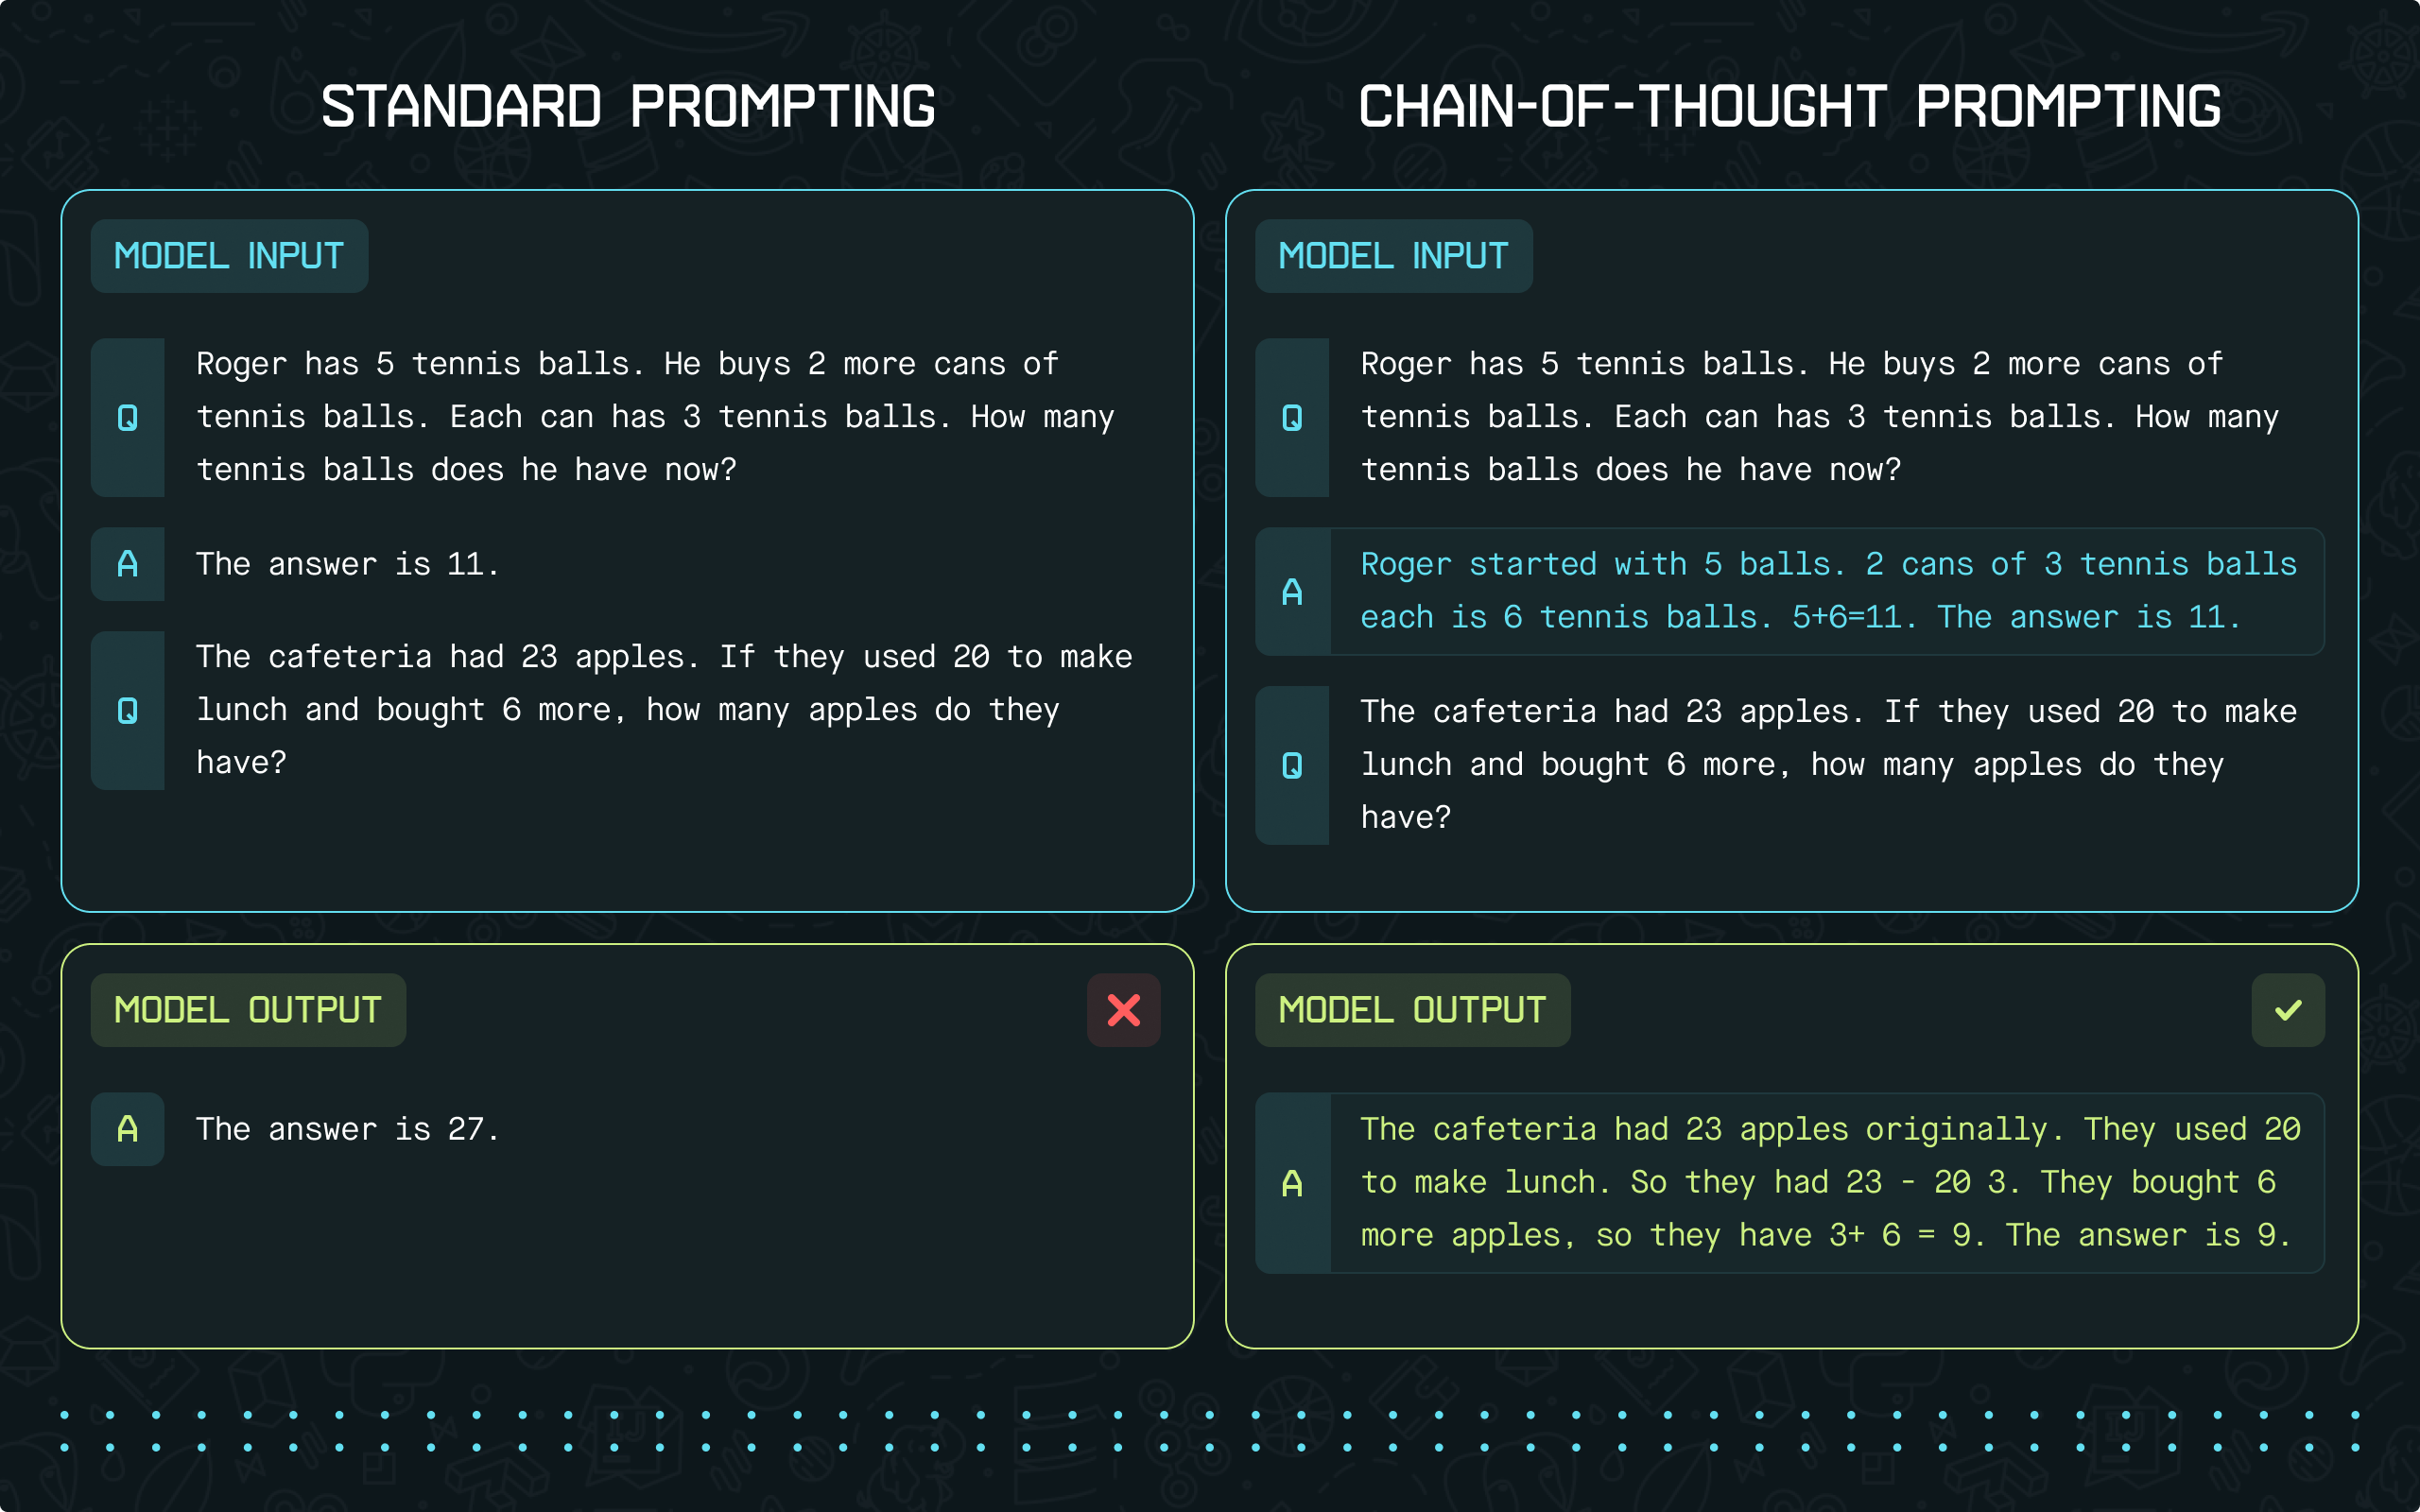
Combining it with few-shot prompting can enhance results for complex tasks that demand reasoning before responding:
(🤓) ↦ Calculate the total cost of apples and oranges, given their individual prices and quantities.
Example 1
Problem: If you buy 5 pencils at $2 each, what is the total cost?
Solution: 5 pencils * $2 each = $10. So, the total cost is $10.
Example 2
Problem: If you buy 3 notebooks at $3 each and 2 pens at $1 each, what is the total cost?
Solution: 3 notebooks * $3 each = $9 and 2 pens * $1 each = $2. Total cost = $9 + $2 = $11.
Problem: If you buy 4 apples at $1.50 each and 5 oranges at $2 each, what is the total cost?
(🤖) ↦
First, calculate the cost of the apples. 4 apples * $1.50 each = $6.
Next, calculate the cost of the oranges. 5 oranges * $2 each = $10.
Finally, add the cost of apples and oranges together. $6 + $10 = $16.
So, the total cost is $16.
Self-Consistency Prompting
SELF-CONSISTENCY PROMPTING
Self-Consistency Prompting (CoT) in LLM involves generating multiple answers to ensure reliability and consistency in responses.
This method involves presenting a question in varied forms to LLM, producing different answers. A few-shot chain of thought technique generates a range of reasoning paths. The final response is determined by selecting the most frequent or consistent answer from the pool of solutions generated across all question versions.
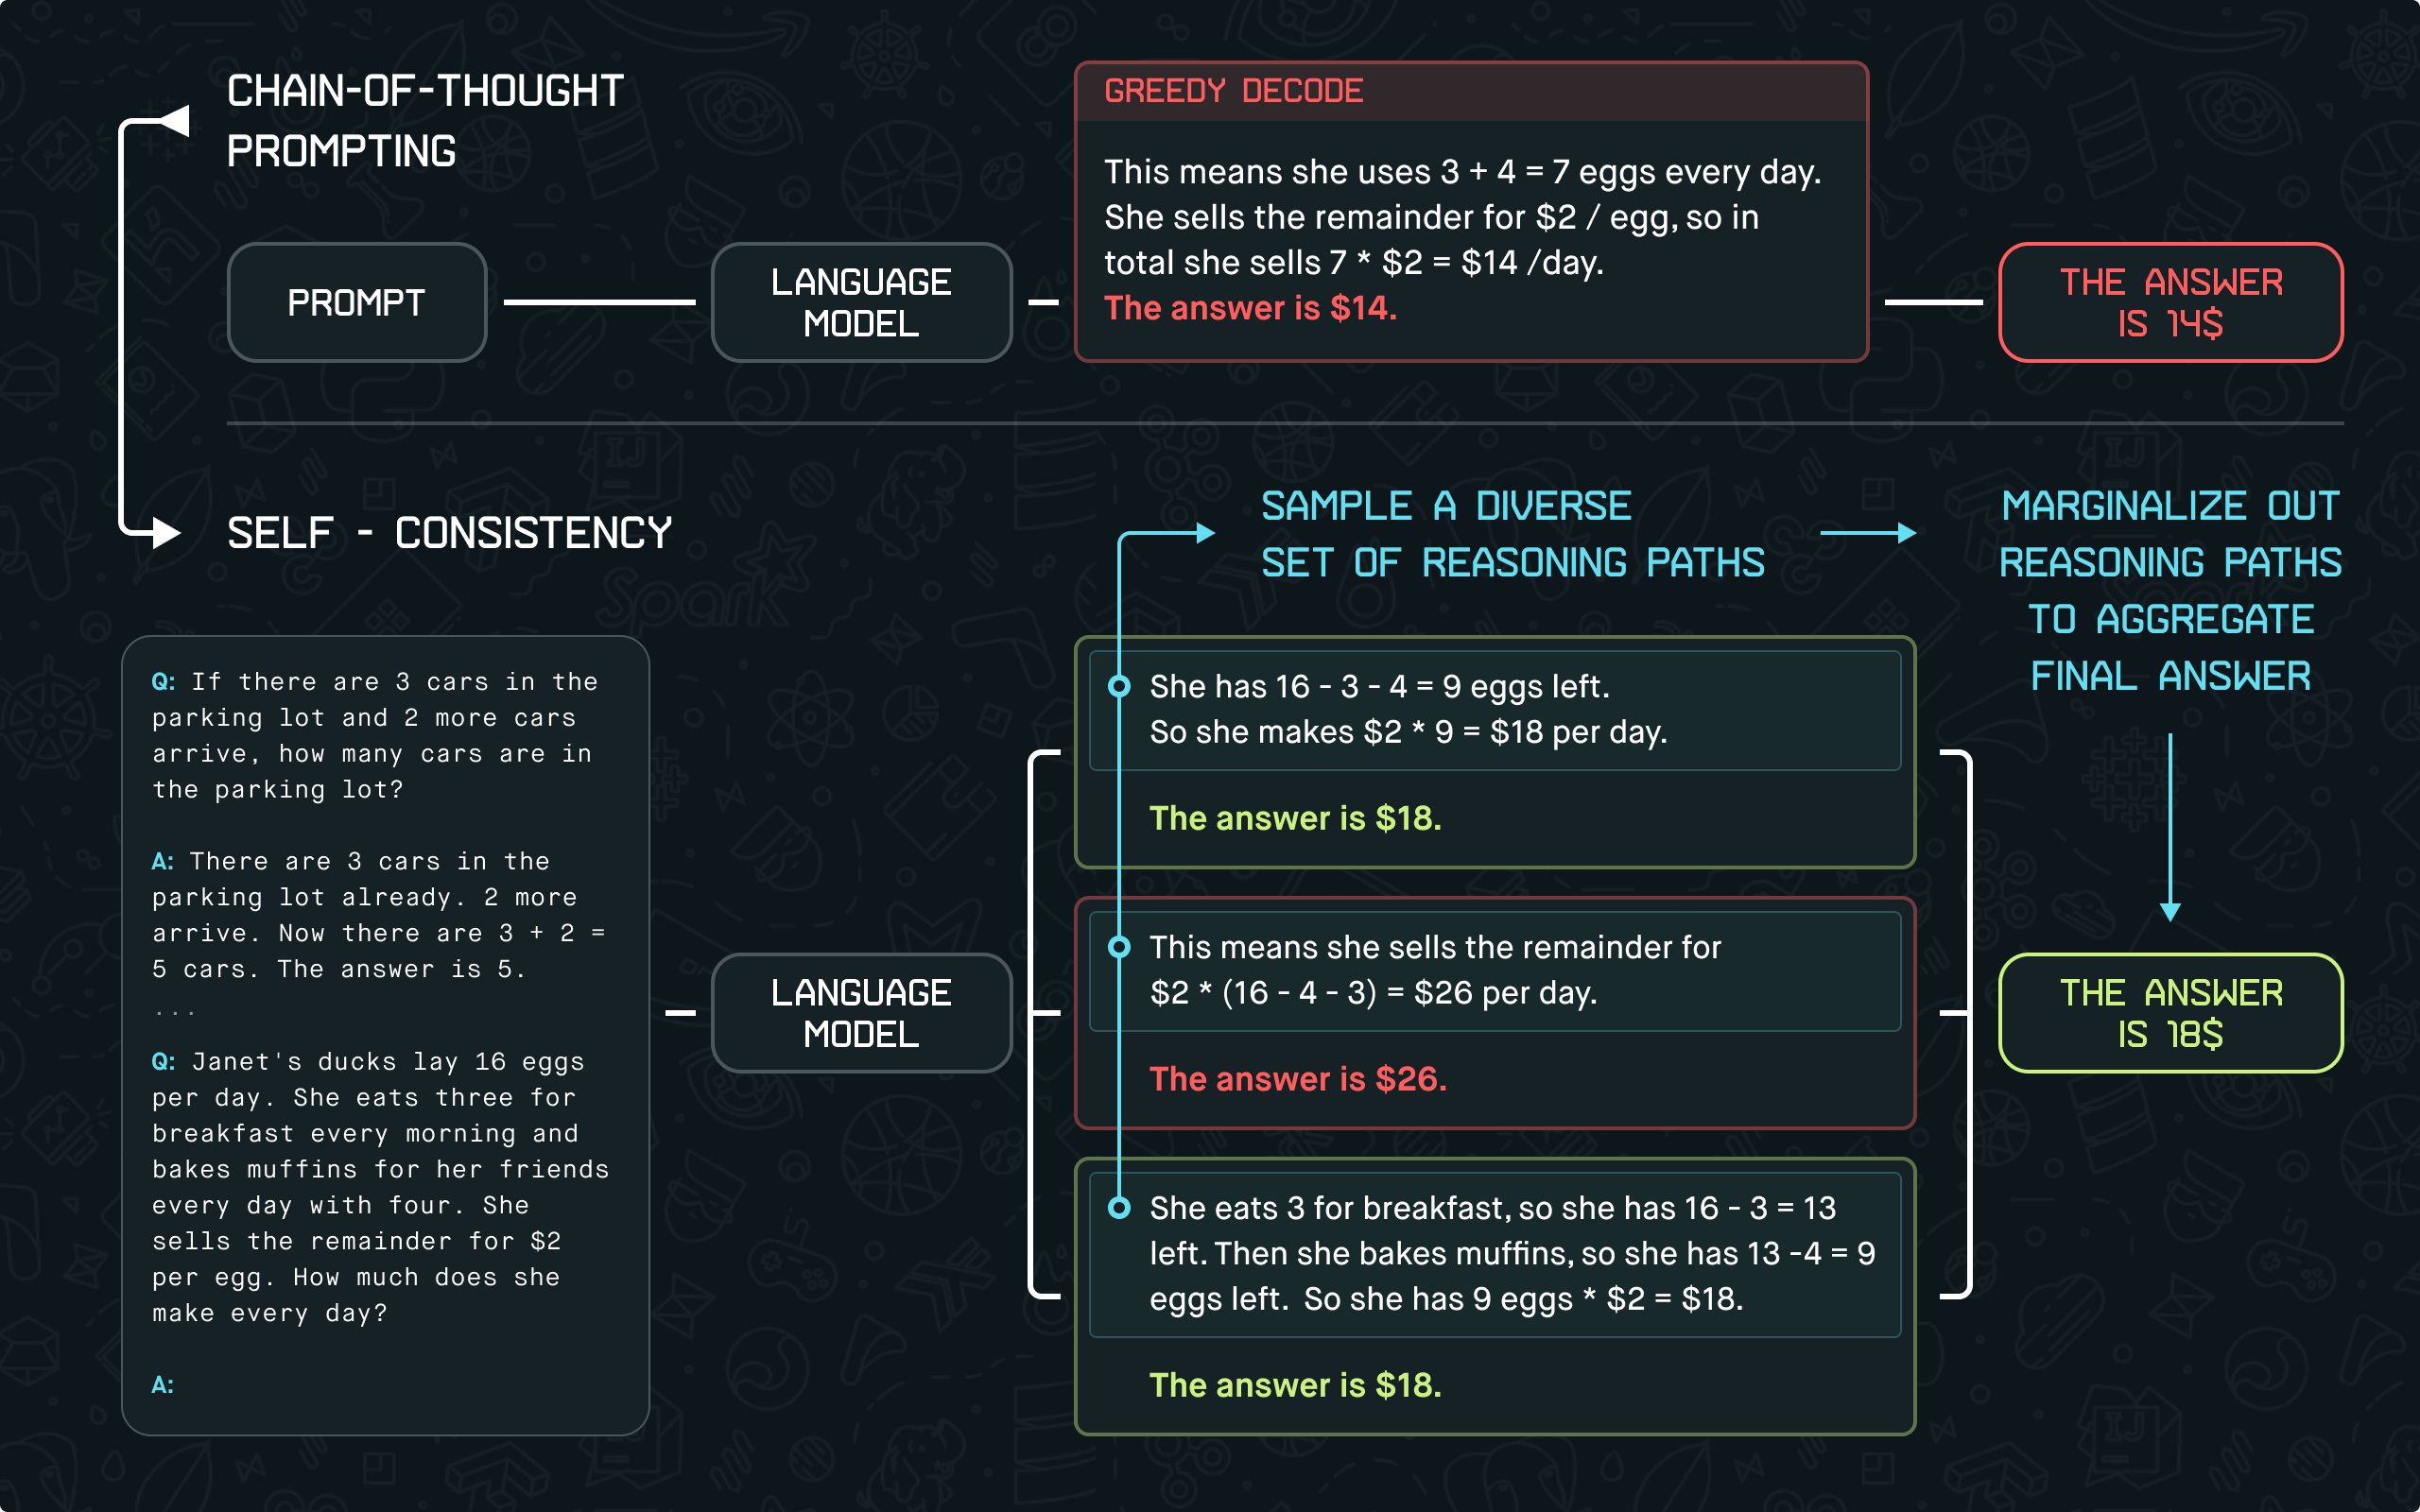
Let's try the following example for arithmetic reasoning:
(🤓) ↦ I have 12 apples. I gave 6 apples to my daughter. How many apples do I have left?
(🤖) ↦ I have 6 apples.
The model would first generate a diverse set of reasoning paths to generate this answer. For example, one reasoning path might be:
- I have 12 apples.
- I gave 6 apples to my daughter.
- Therefore, I have 6 apples left.
Another reasoning path might be:
- At the start, I had 12 apples.
- I gave half of my apples to my daughter.
- Therefore, I have 6 apples left.
The model uses its world knowledge and prompt information to determine the most coherent response, concluding with 6 apples remaining in the given scenario.
Generated Knowledge Prompting
GENERATED KNOWLEDGE PROMPTING
Generated Knowledge Prompting is a technique where models use their training to generate new insights. This method prompts the LLM to synthesize information, drawing on learned patterns and relationships to create original content. For example, it could help generate innovative marketing strategies by combining its understanding of marketing and consumer trends.
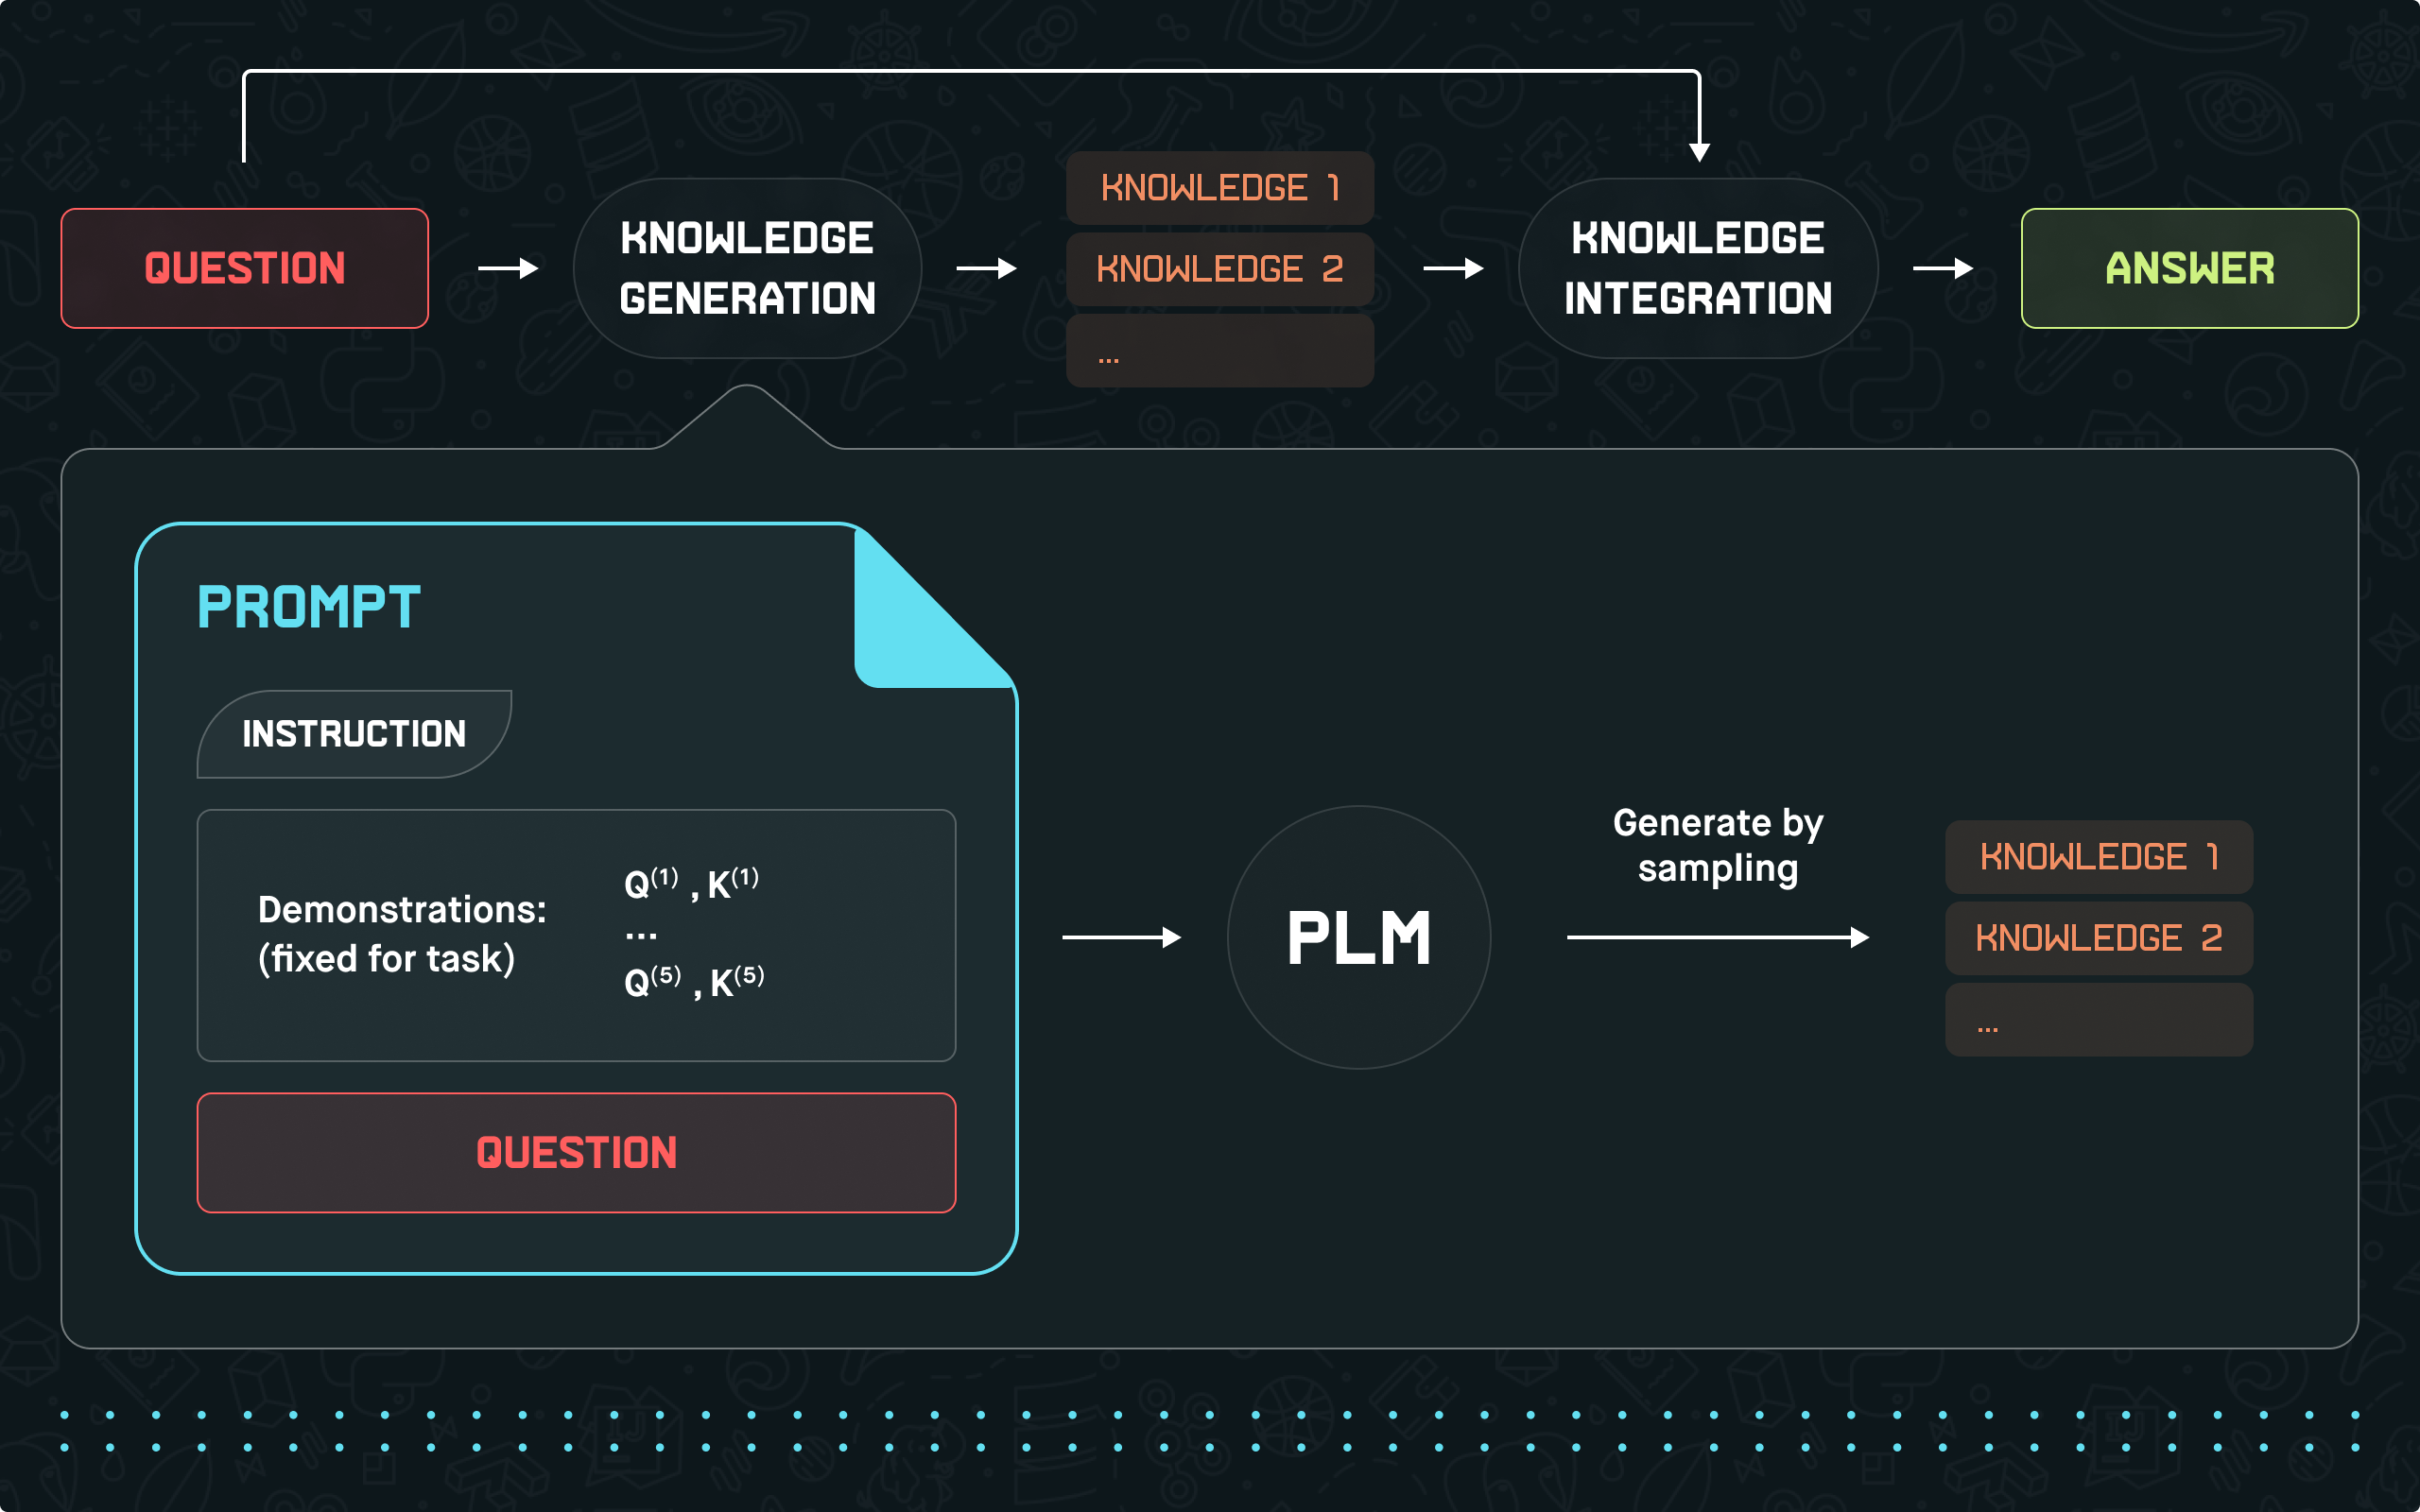
Here's an example to illustrate how GKP works.
LLM's first response:
(🤓) ↦ Explain the basics of quantum computing.
(🤖) ↦ Quantum computing is a type of computation that uses quantum-mechanical phenomena, such as superposition and entanglement, to perform operations on data. Unlike classical computers, which use bits as units of data, quantum computers use quantum bits or qubits. This allows them to process large amounts of data more efficiently for specific problems.
Generated Knowledge Prompting (using the first LLM's response):
(🤓) ↦ Can you provide a real-world application where quantum computing outperforms classical computing?
Knowledge: Quantum computing is a type of computation that uses quantum-mechanical phenomena, such as superposition and entanglement, to perform operations on data. Unlike classical computers, which use bits as units of data, quantum computers use quantum bits or qubits. This allows them to process large amounts of data more efficiently for specific problems.
(🤖) ↦ One significant area where quantum computing outperforms classical computing is in cryptography. Quantum computers can potentially break widely used cryptographic algorithms much faster than classical computers. Another area is drug discovery and materials science, where they can simulate molecular interactions much more quickly, aiding in developing new drugs and materials rapidly.
This iterative process can continue, delving deeper into the topic or branching out into related areas, guided by the user's interests or the needs of the conversation.
Tree Of Thoughts
TREE OF THOUGHTS
The Tree of Thoughts (ToT) prompting in LLM uses a decision tree-like structure for multi-layered reasoning, enabling them to thoroughly explore topics with branches representing different ideas. This method is effective for complex problems and diverse viewpoints. For example, in solving an environmental issue, LLM might consider various branches like technology, policy, and public awareness, each with detailed sub-branches.
In ToT prompting, the model is guided to create a hierarchical framework of reasoning, similar to a decision tree. Each "branch" of this tree represents a distinct line of thought or a specific aspect of the larger problem. These branches can further subdivide into "sub-branches," delving deeper into each aspect. This structured approach enables the systematic analysis of various components of a complex issue, considering how each part interacts with and impacts the others.
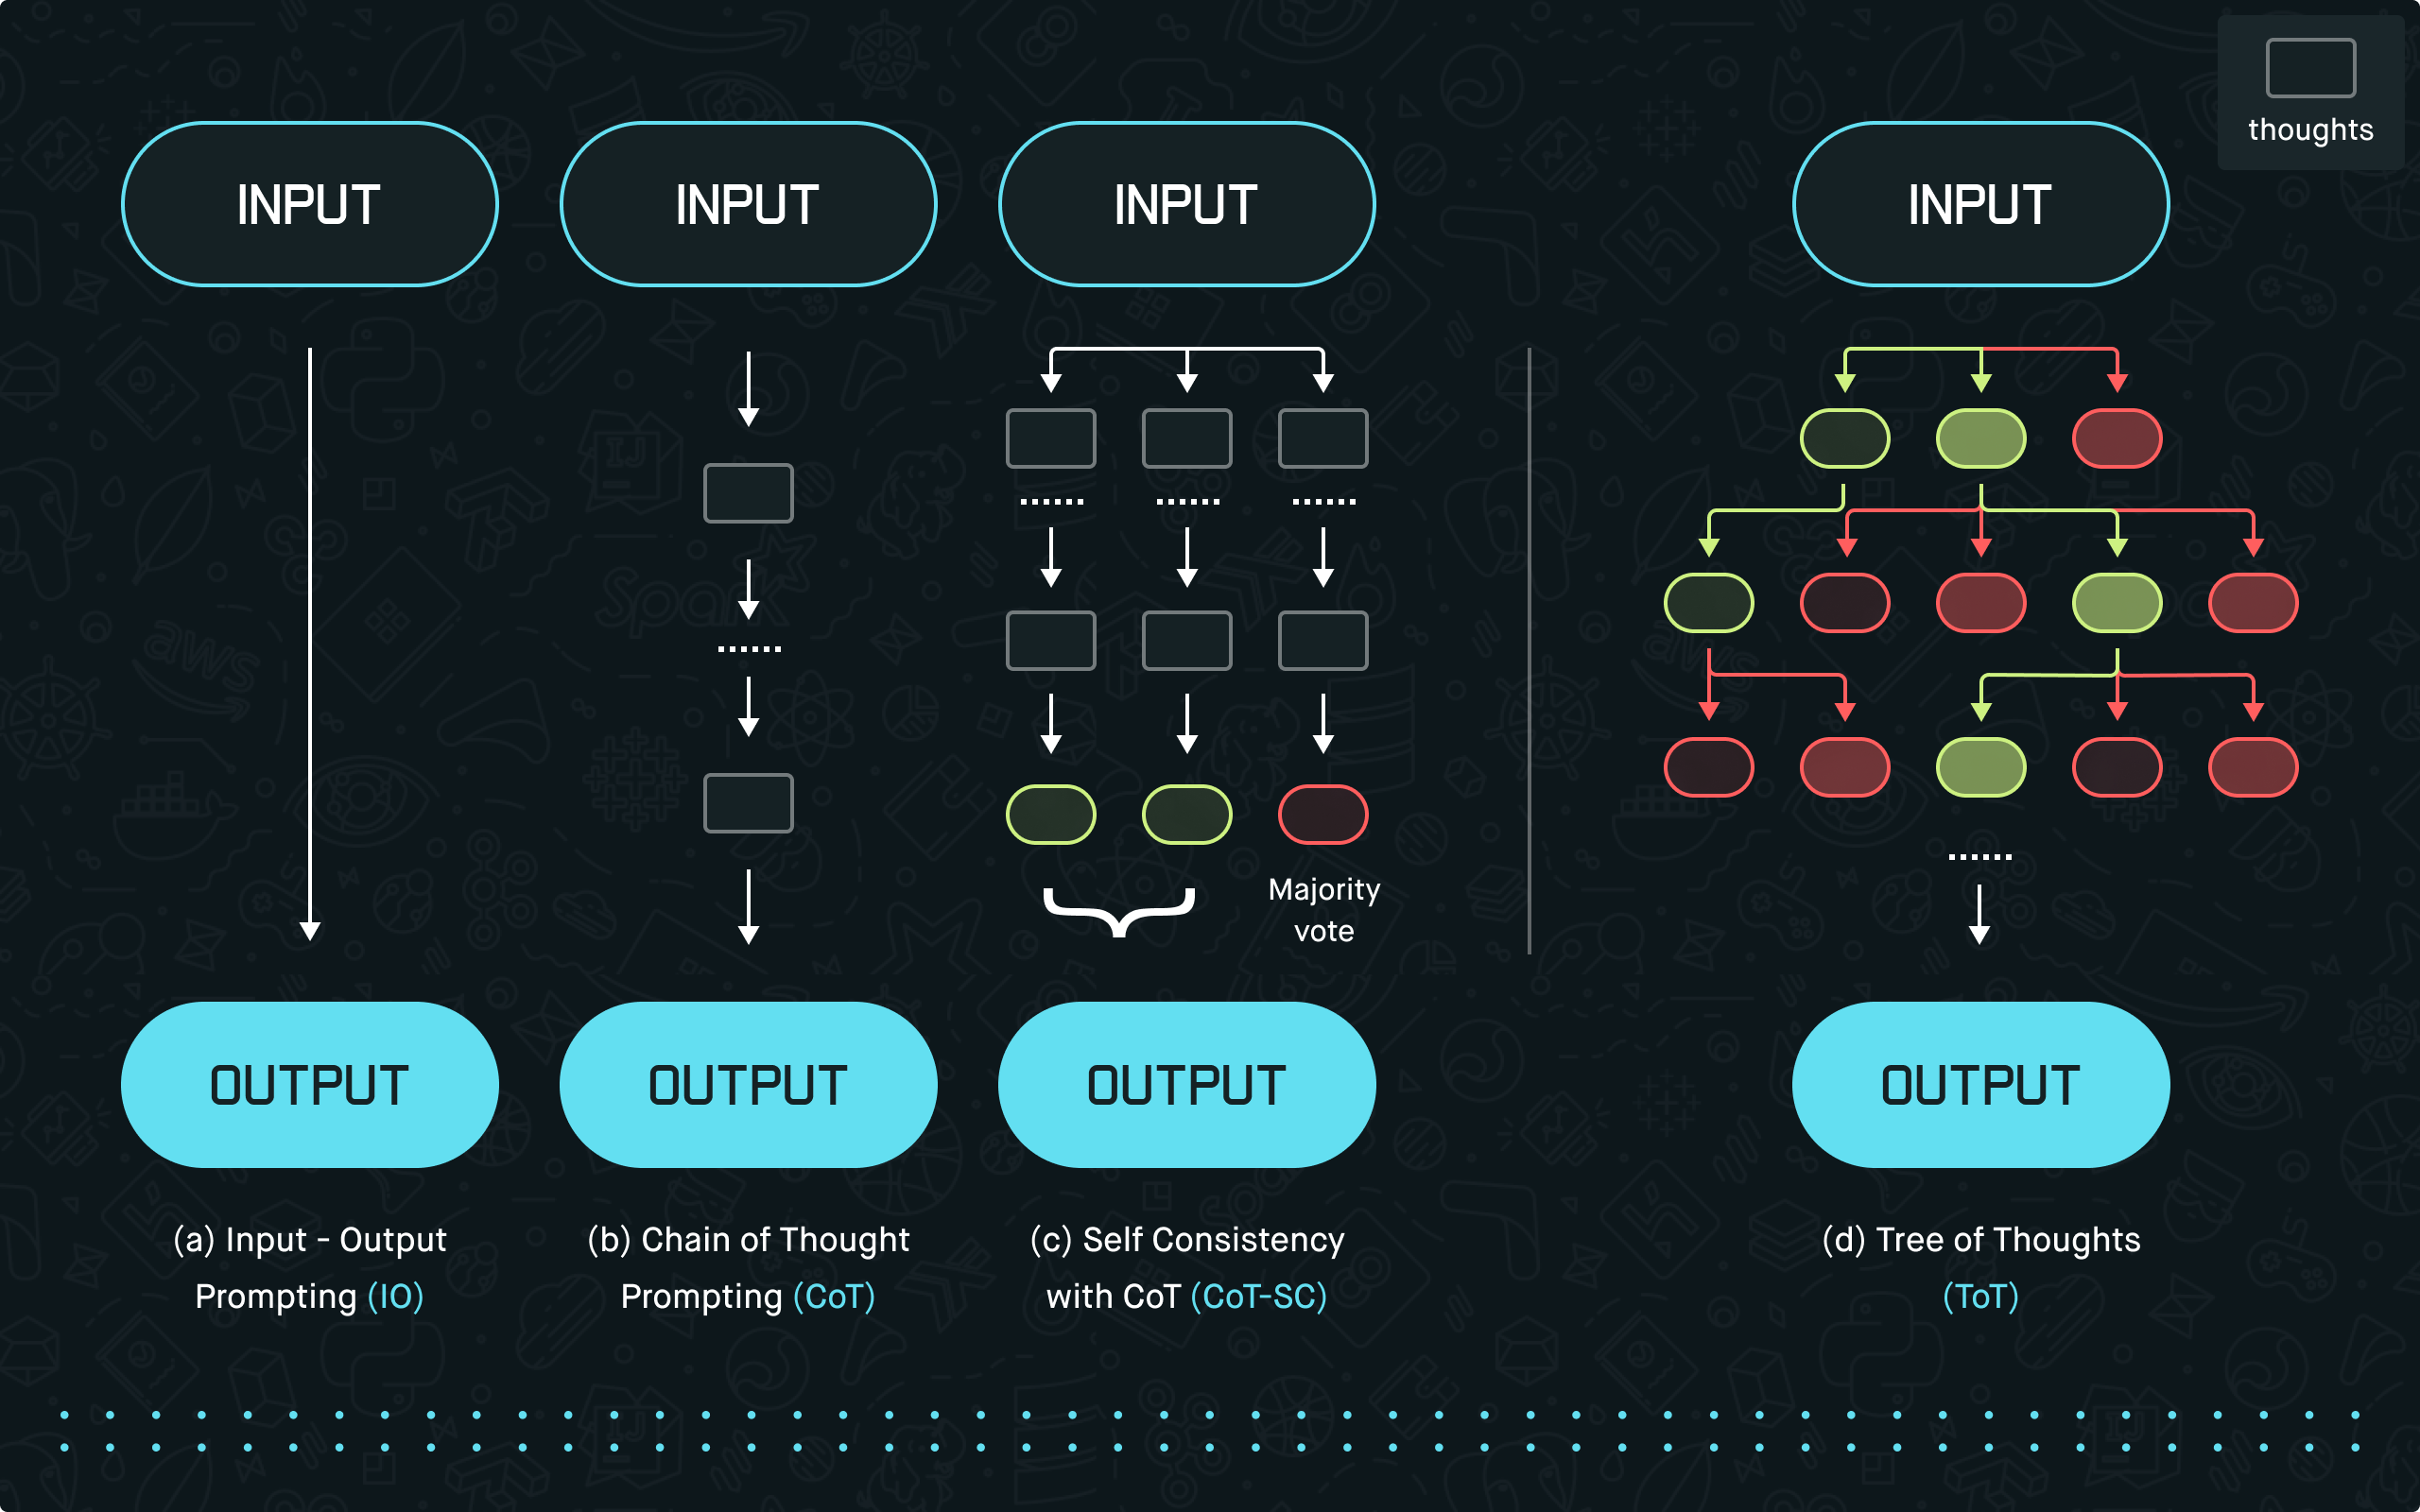
Let’s see the Game of 24 examples of ToT from the original paper, where the goal is to use 4 numbers and basic arithmetic operations to obtain 24. For example, given input “4 9 10 13”, an output could be “(10 - 4) * (13 - 9) = 24”:
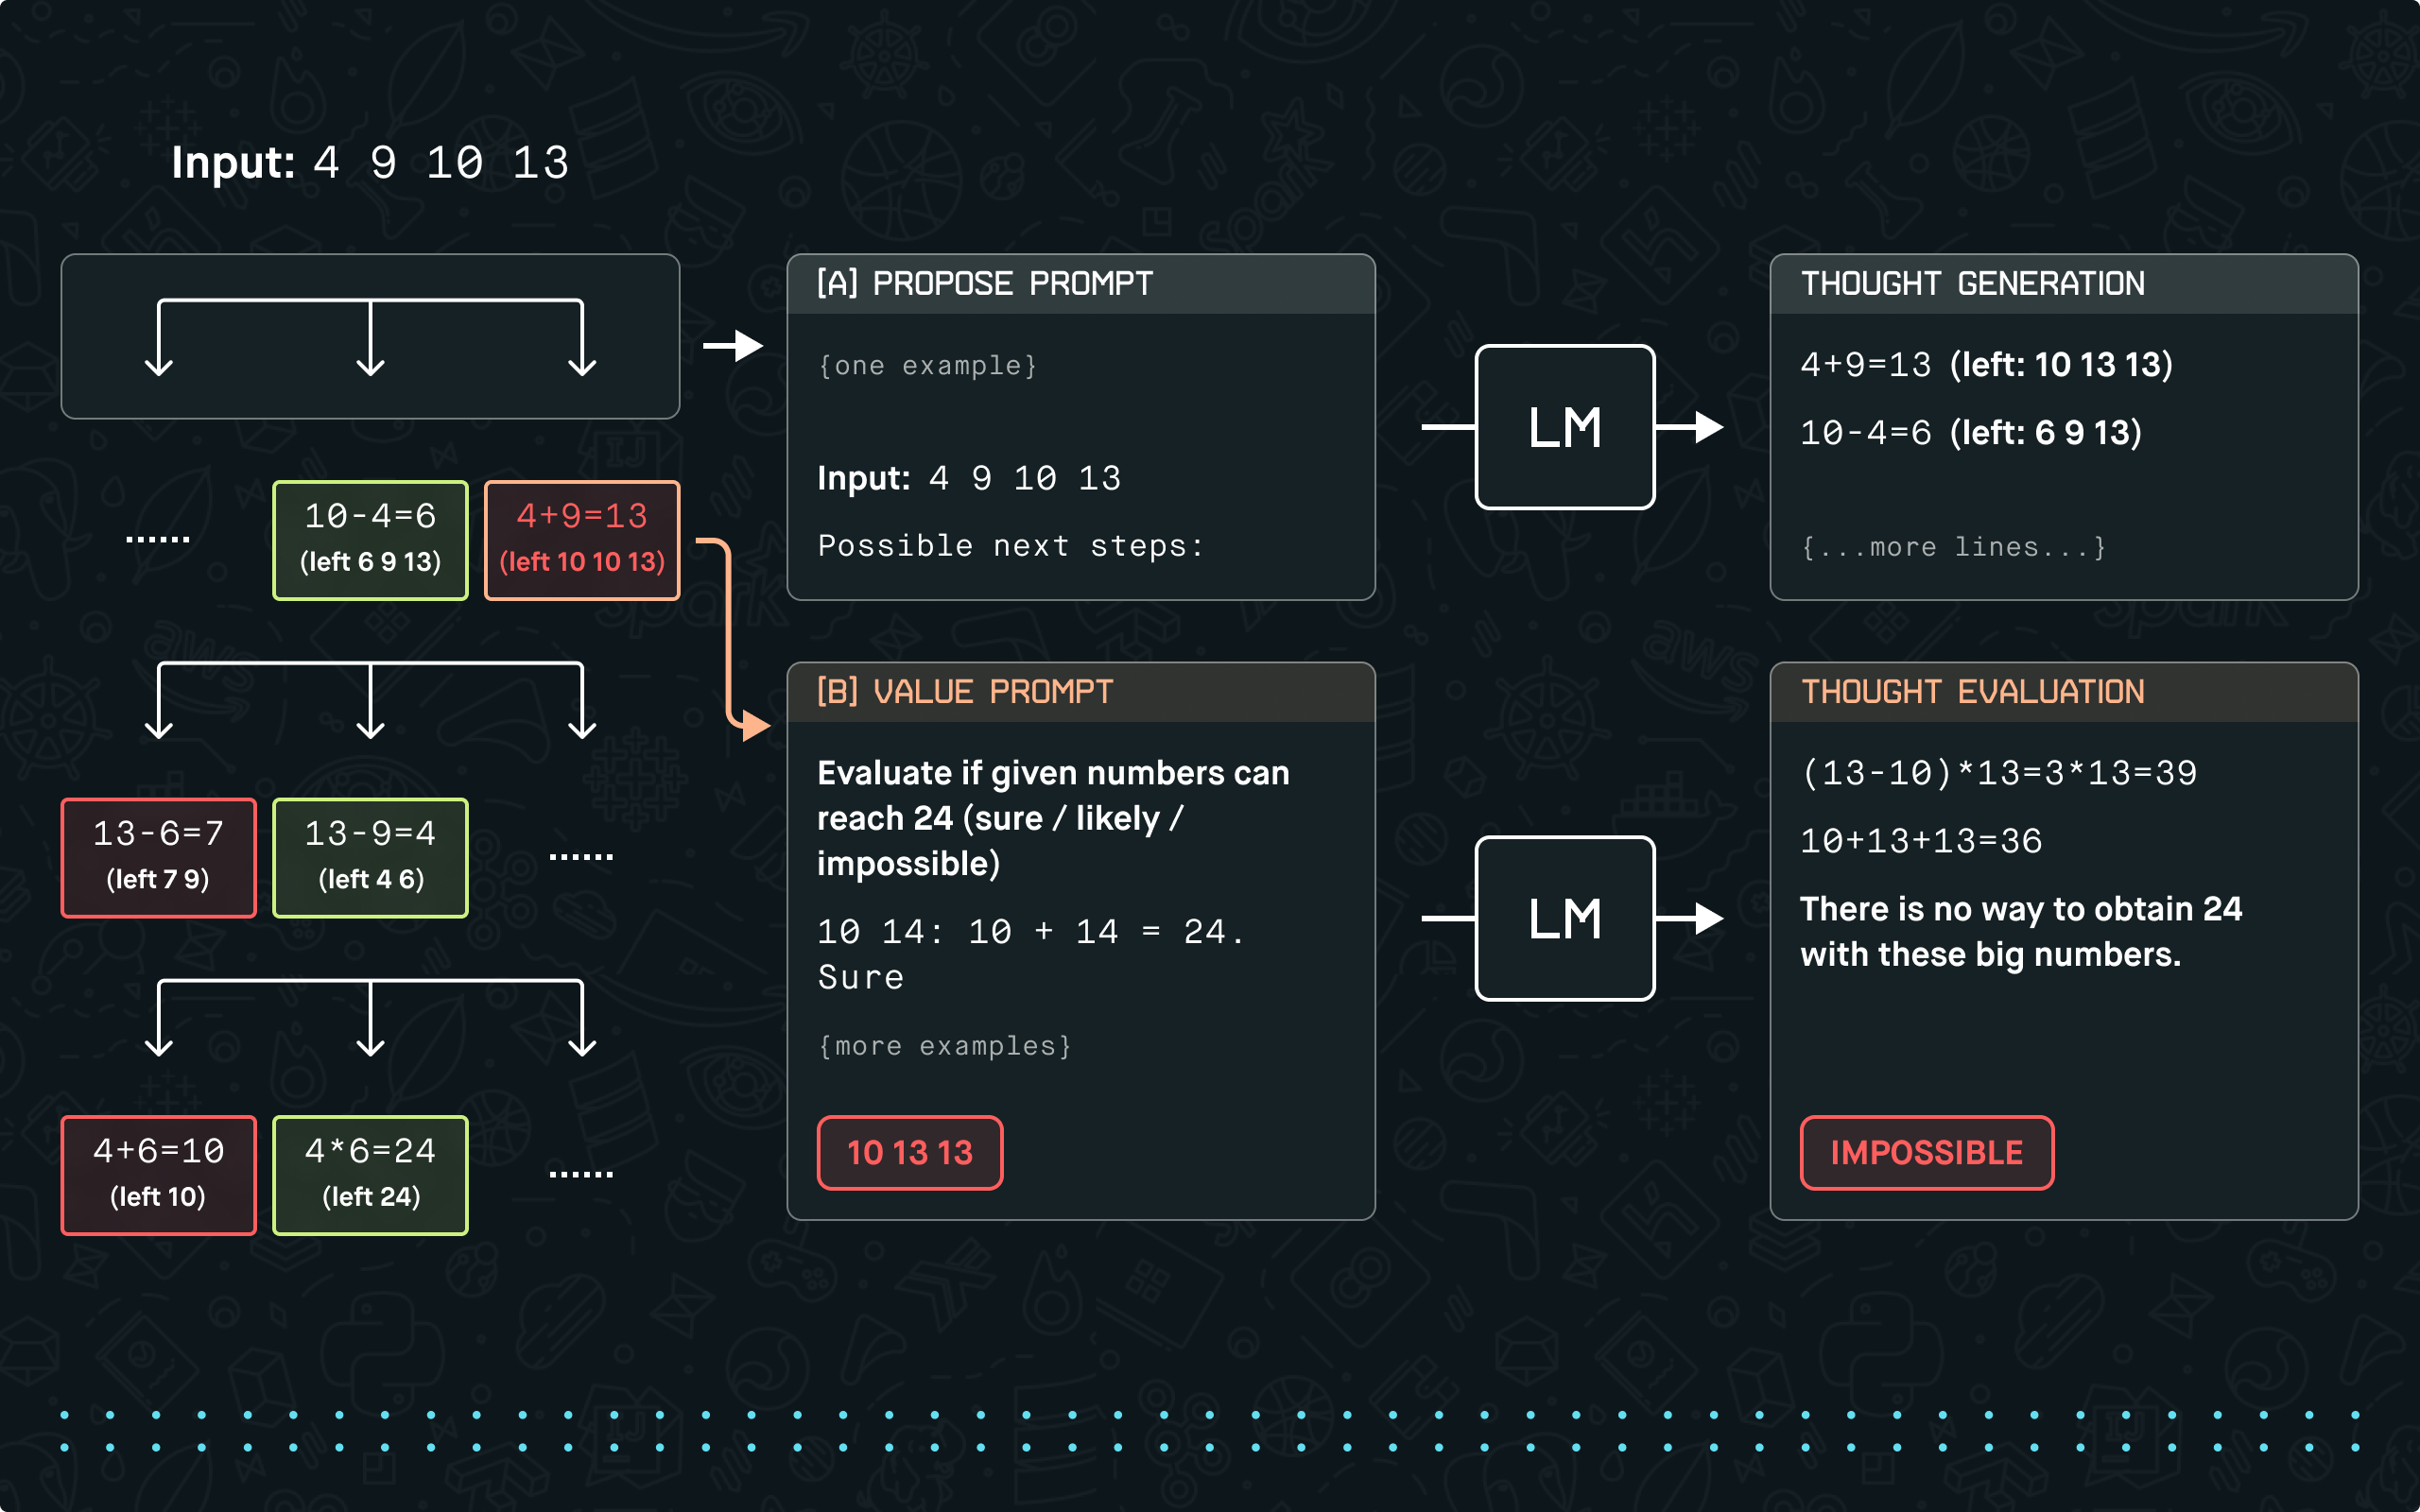
Here is using 2 prompt types to build a tree:
- Propose prompt
This prompt will be used to generate the first depth of the tree and list all the possible solutions at the first level. - Value Prompt
The few-shot LLM prompt for the remaining depths (green and red) to help evaluate if a “24” answer is possible or not.
Retrieval Augmented Generation
RETRIEVAL AUGMENTED GENERATION
Retrieval Augmented Generation (RAG) is a technique that combines the power of traditional large language models with external information retrieval to enhance their response generation capabilities. Models, such as GPT-3 or BERT, are inherently powerful in generating human-like text based on their training data. RAG takes this further by enabling these models to access and integrate external information dynamically, augmenting their knowledge base in real-time.
RAG bridges the gap between traditional LLM and external databases or information sources. When an LLM encounters a query or a topic it's not sufficiently trained on, RAG intervenes by retrieving relevant information from the external source. This information is then incorporated into the model's response generation process, resulting in answers that are not only based on the model's pre-existing knowledge but also enriched with the latest, most relevant external data.
How Retrieval Augmented Generation works:
- Query Processing
The LLM receives and processes the query.
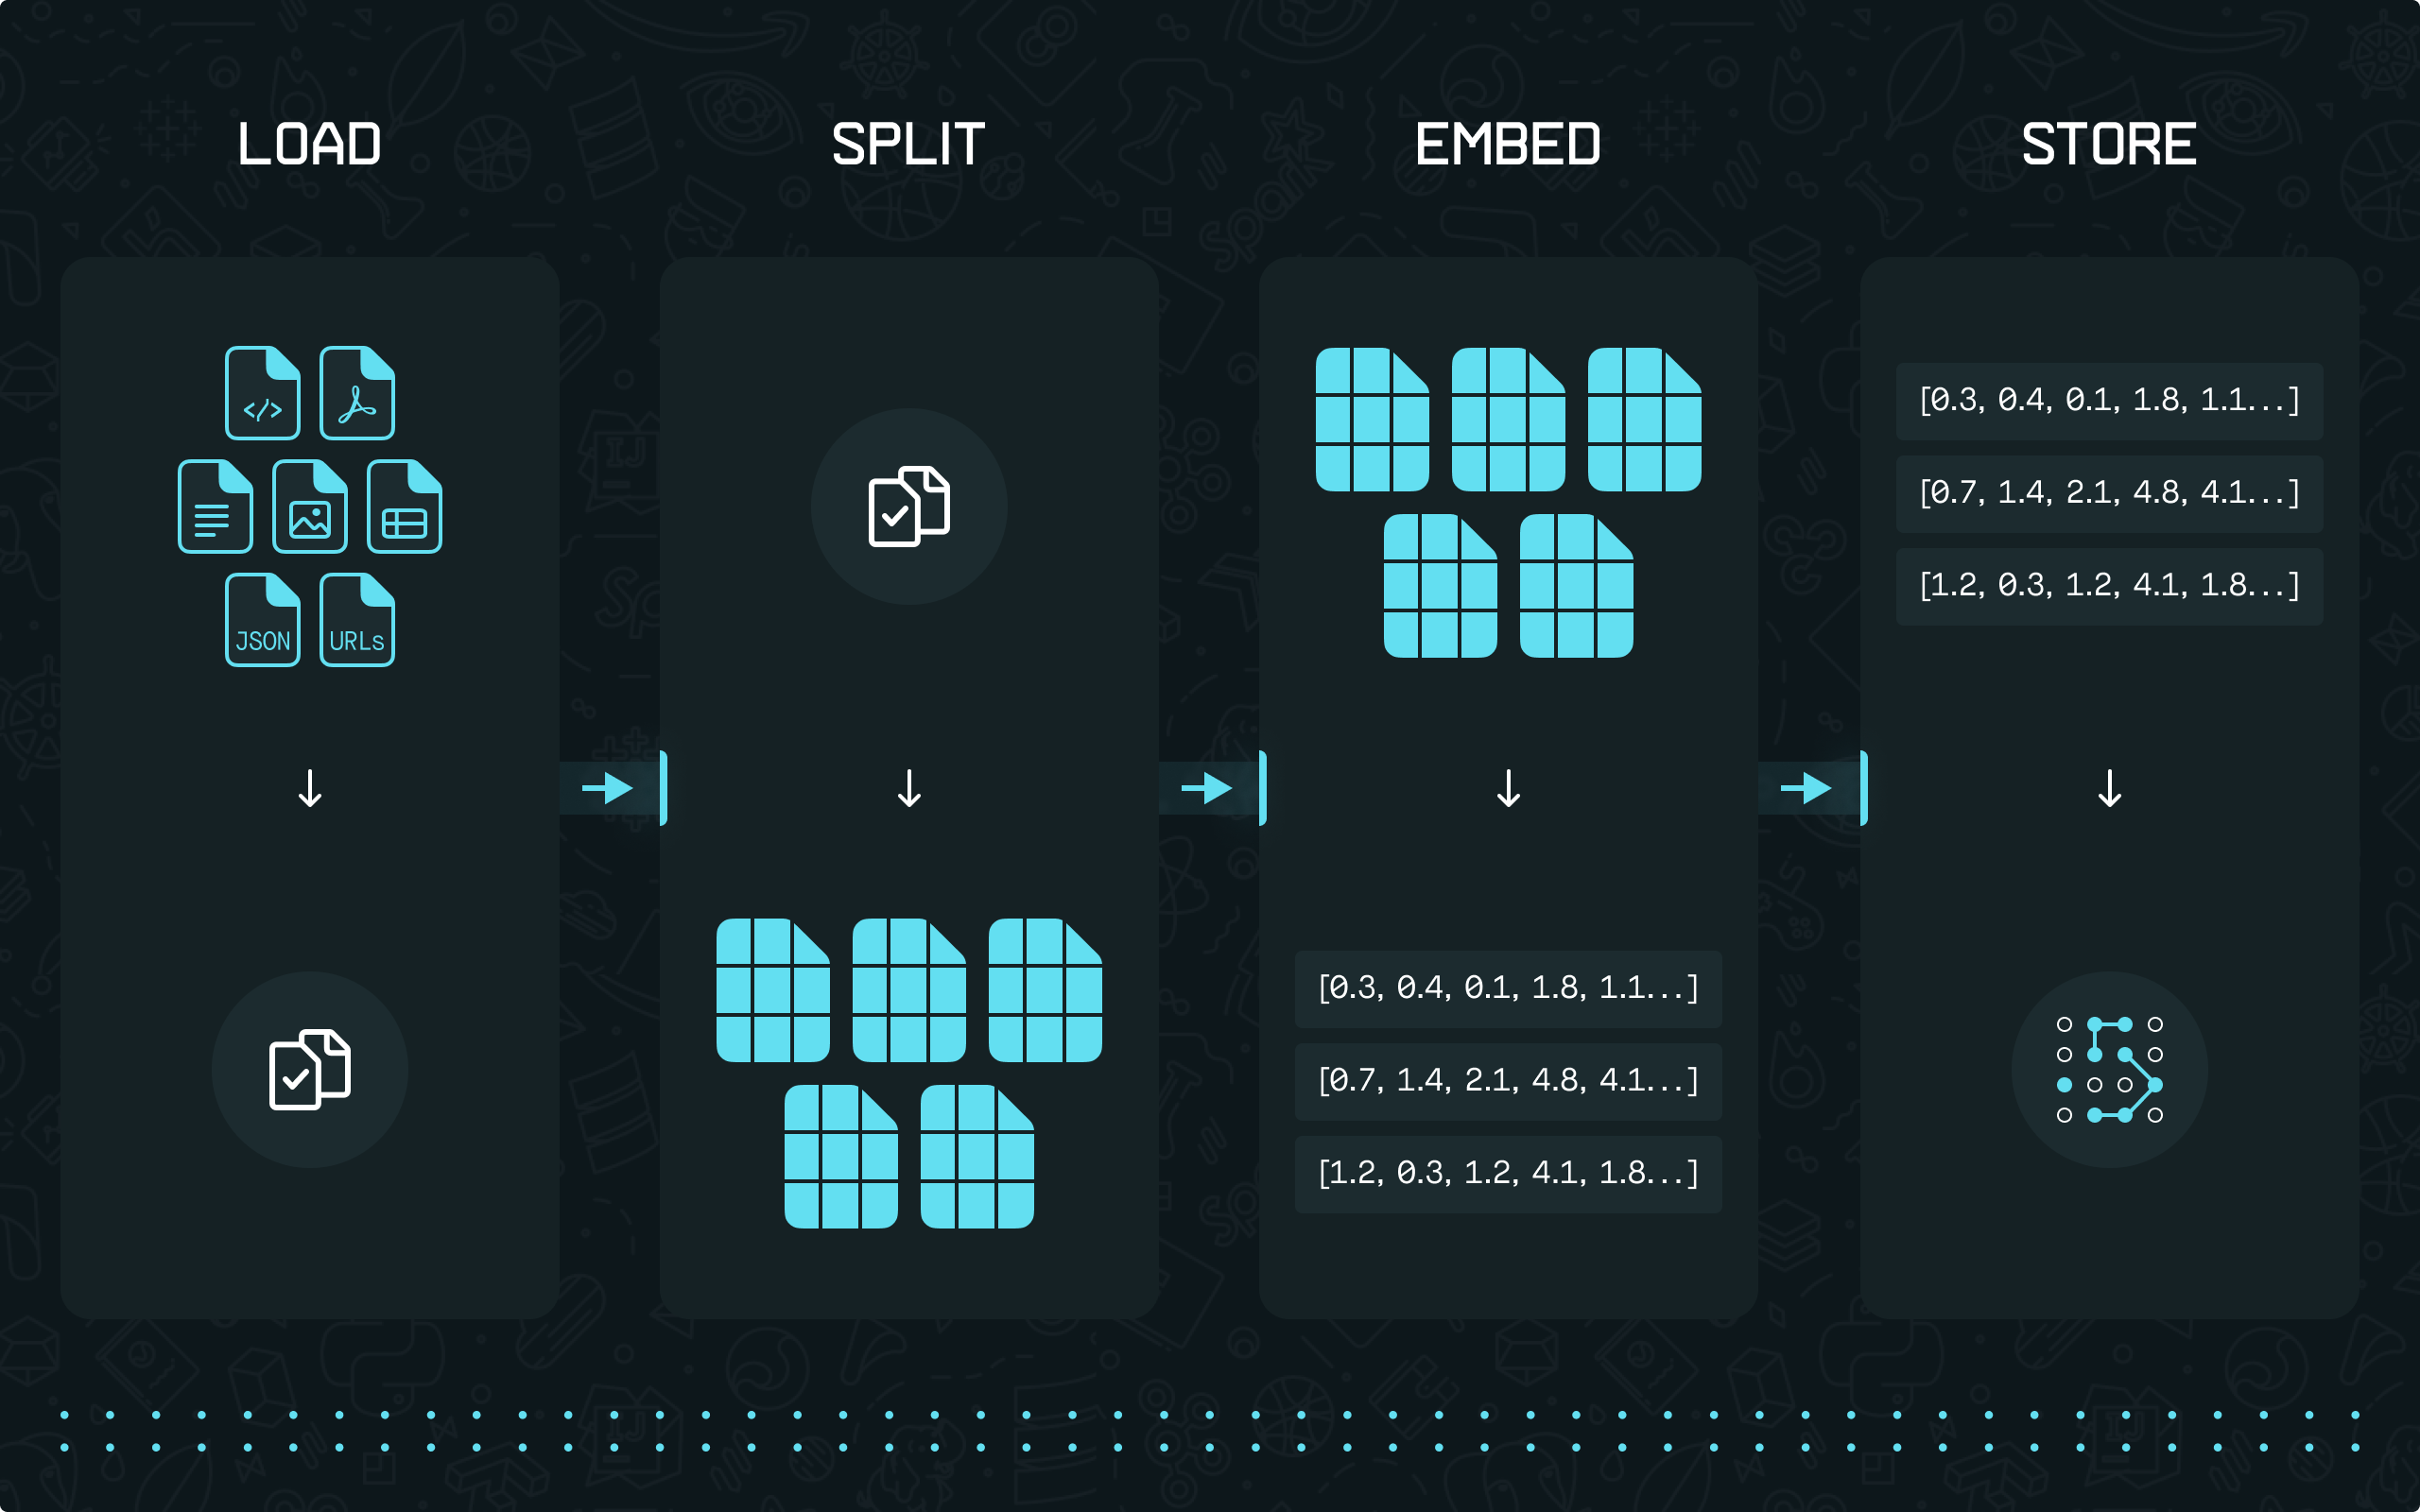
- Information Retrieval
RAG searches an external database or the internet for relevant information. - Response Integration
The retrieved information is integrated with the LLM's knowledge to generate a comprehensive response.
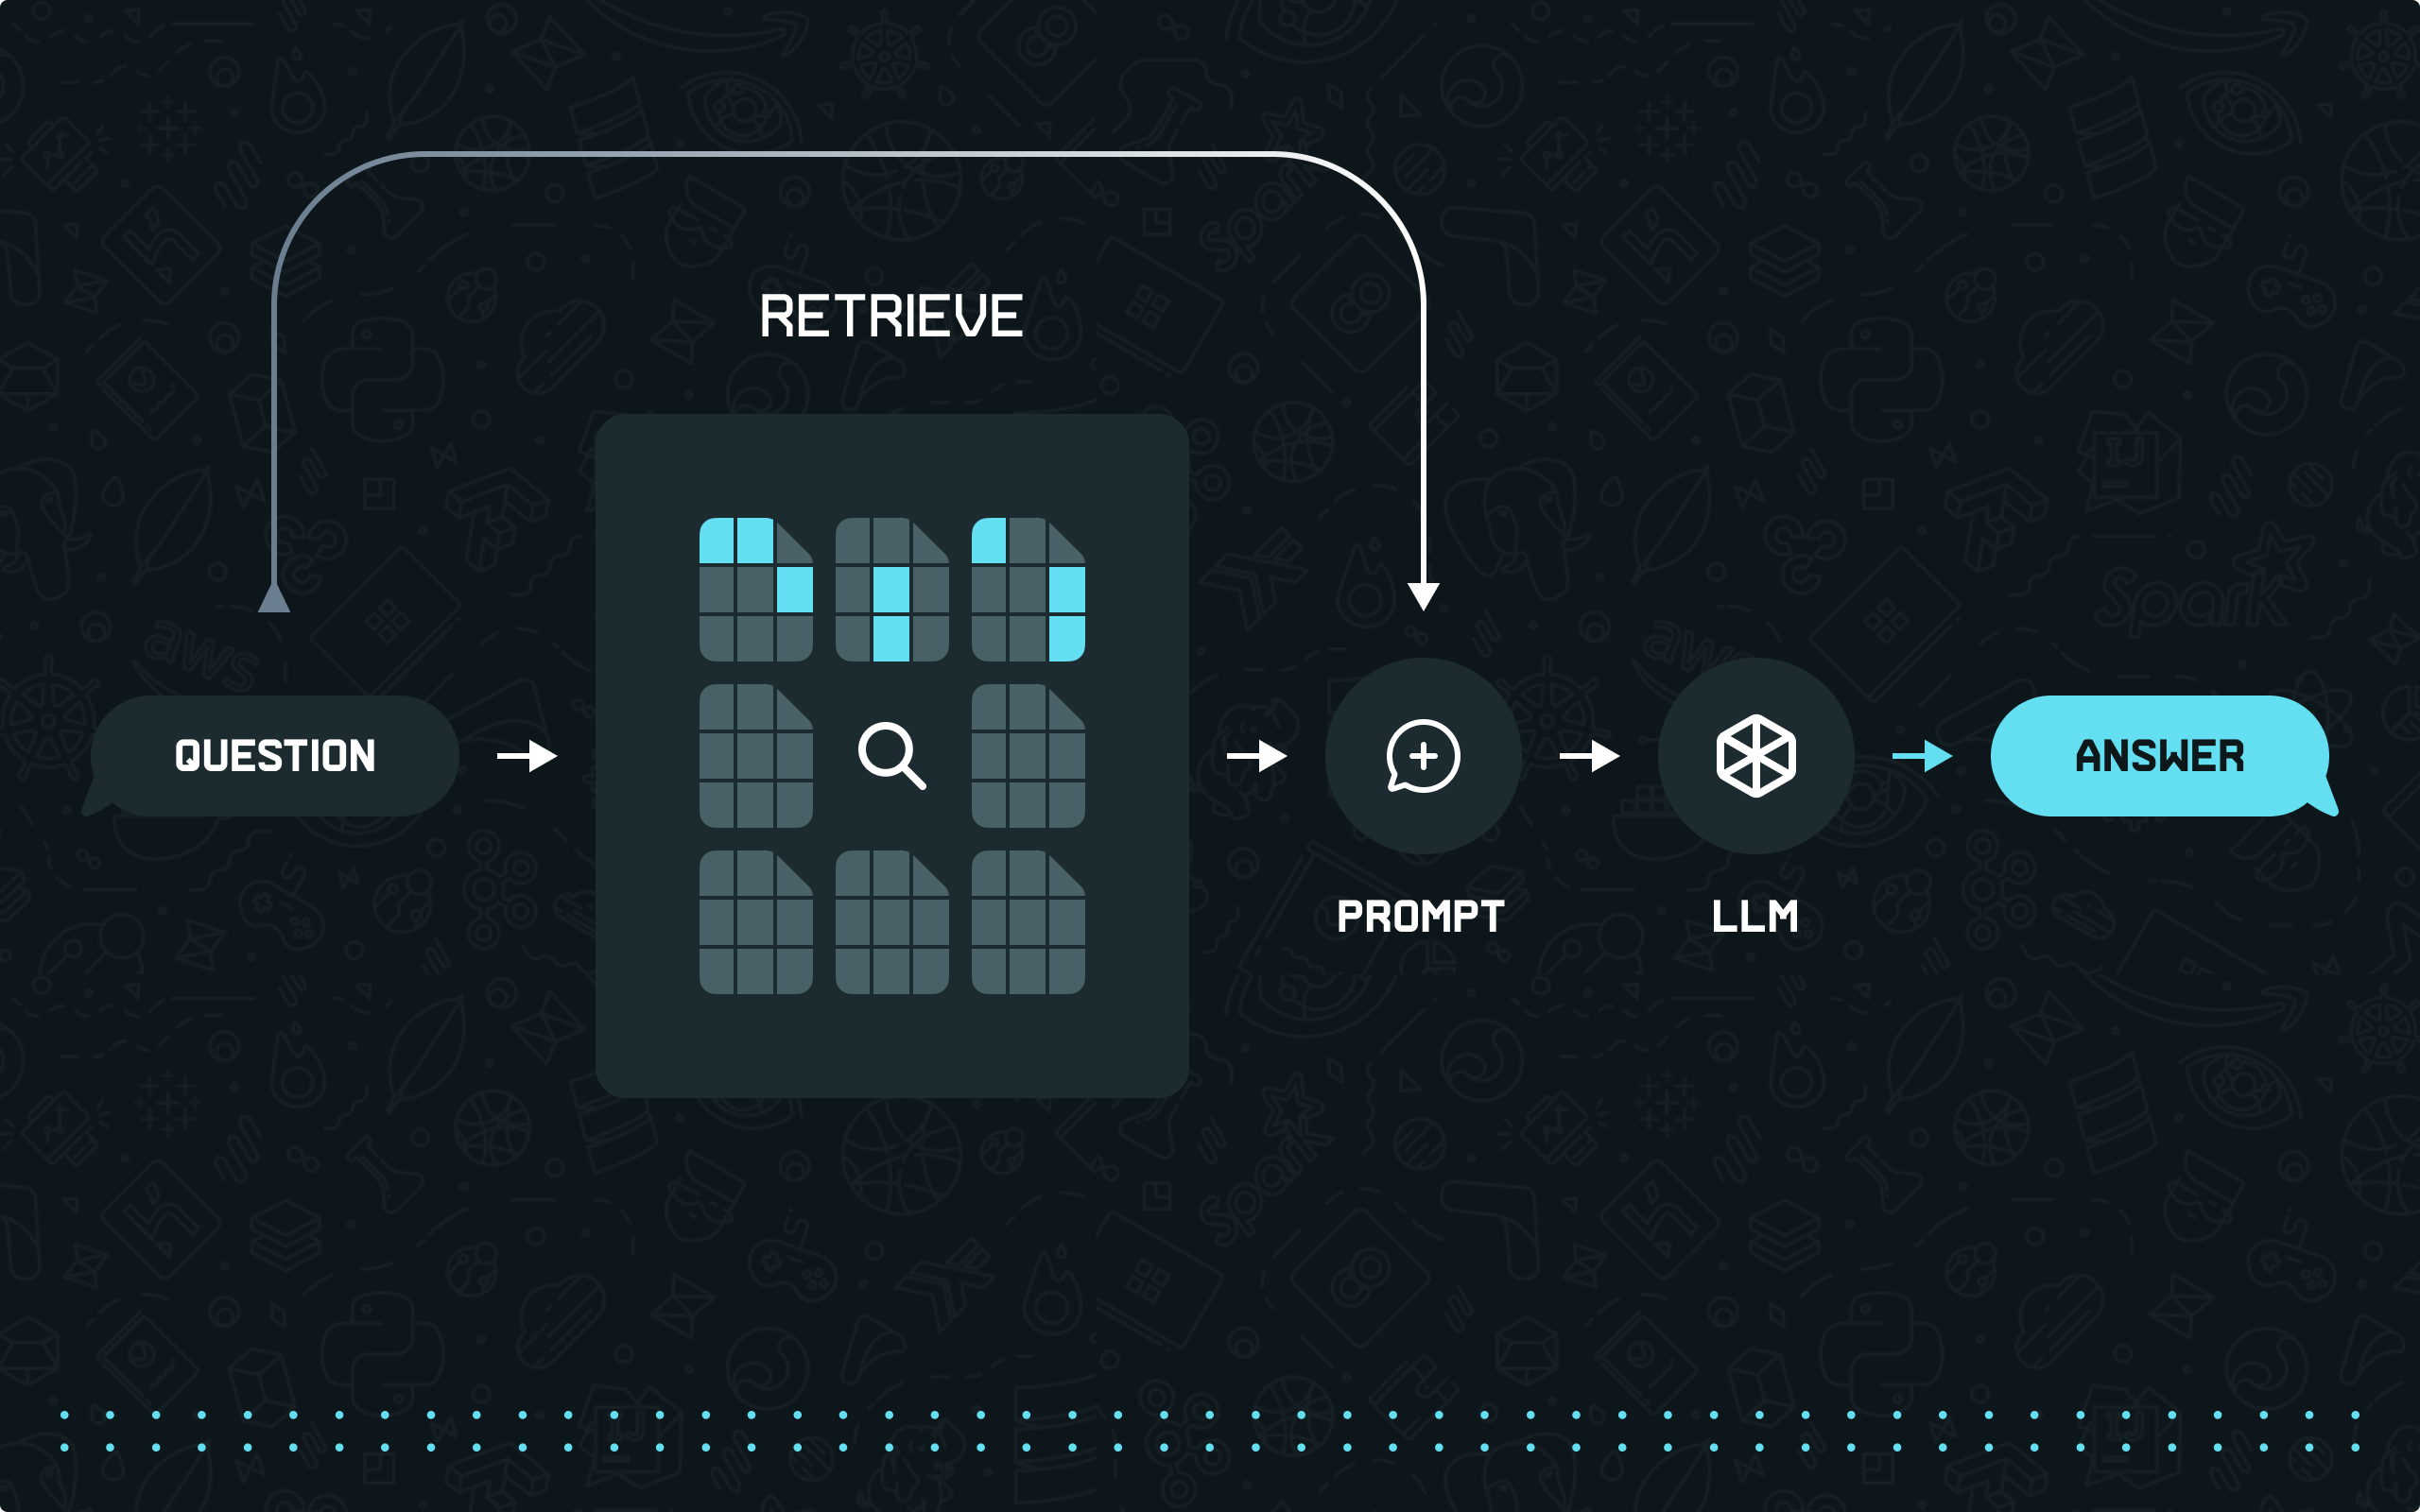
A straightforward example of using retrievers and LLMs for question answering with sources can be found in the LangChain documentation.
Automatic Prompt Engineer
AUTOMATIC PROMPT ENGINEER
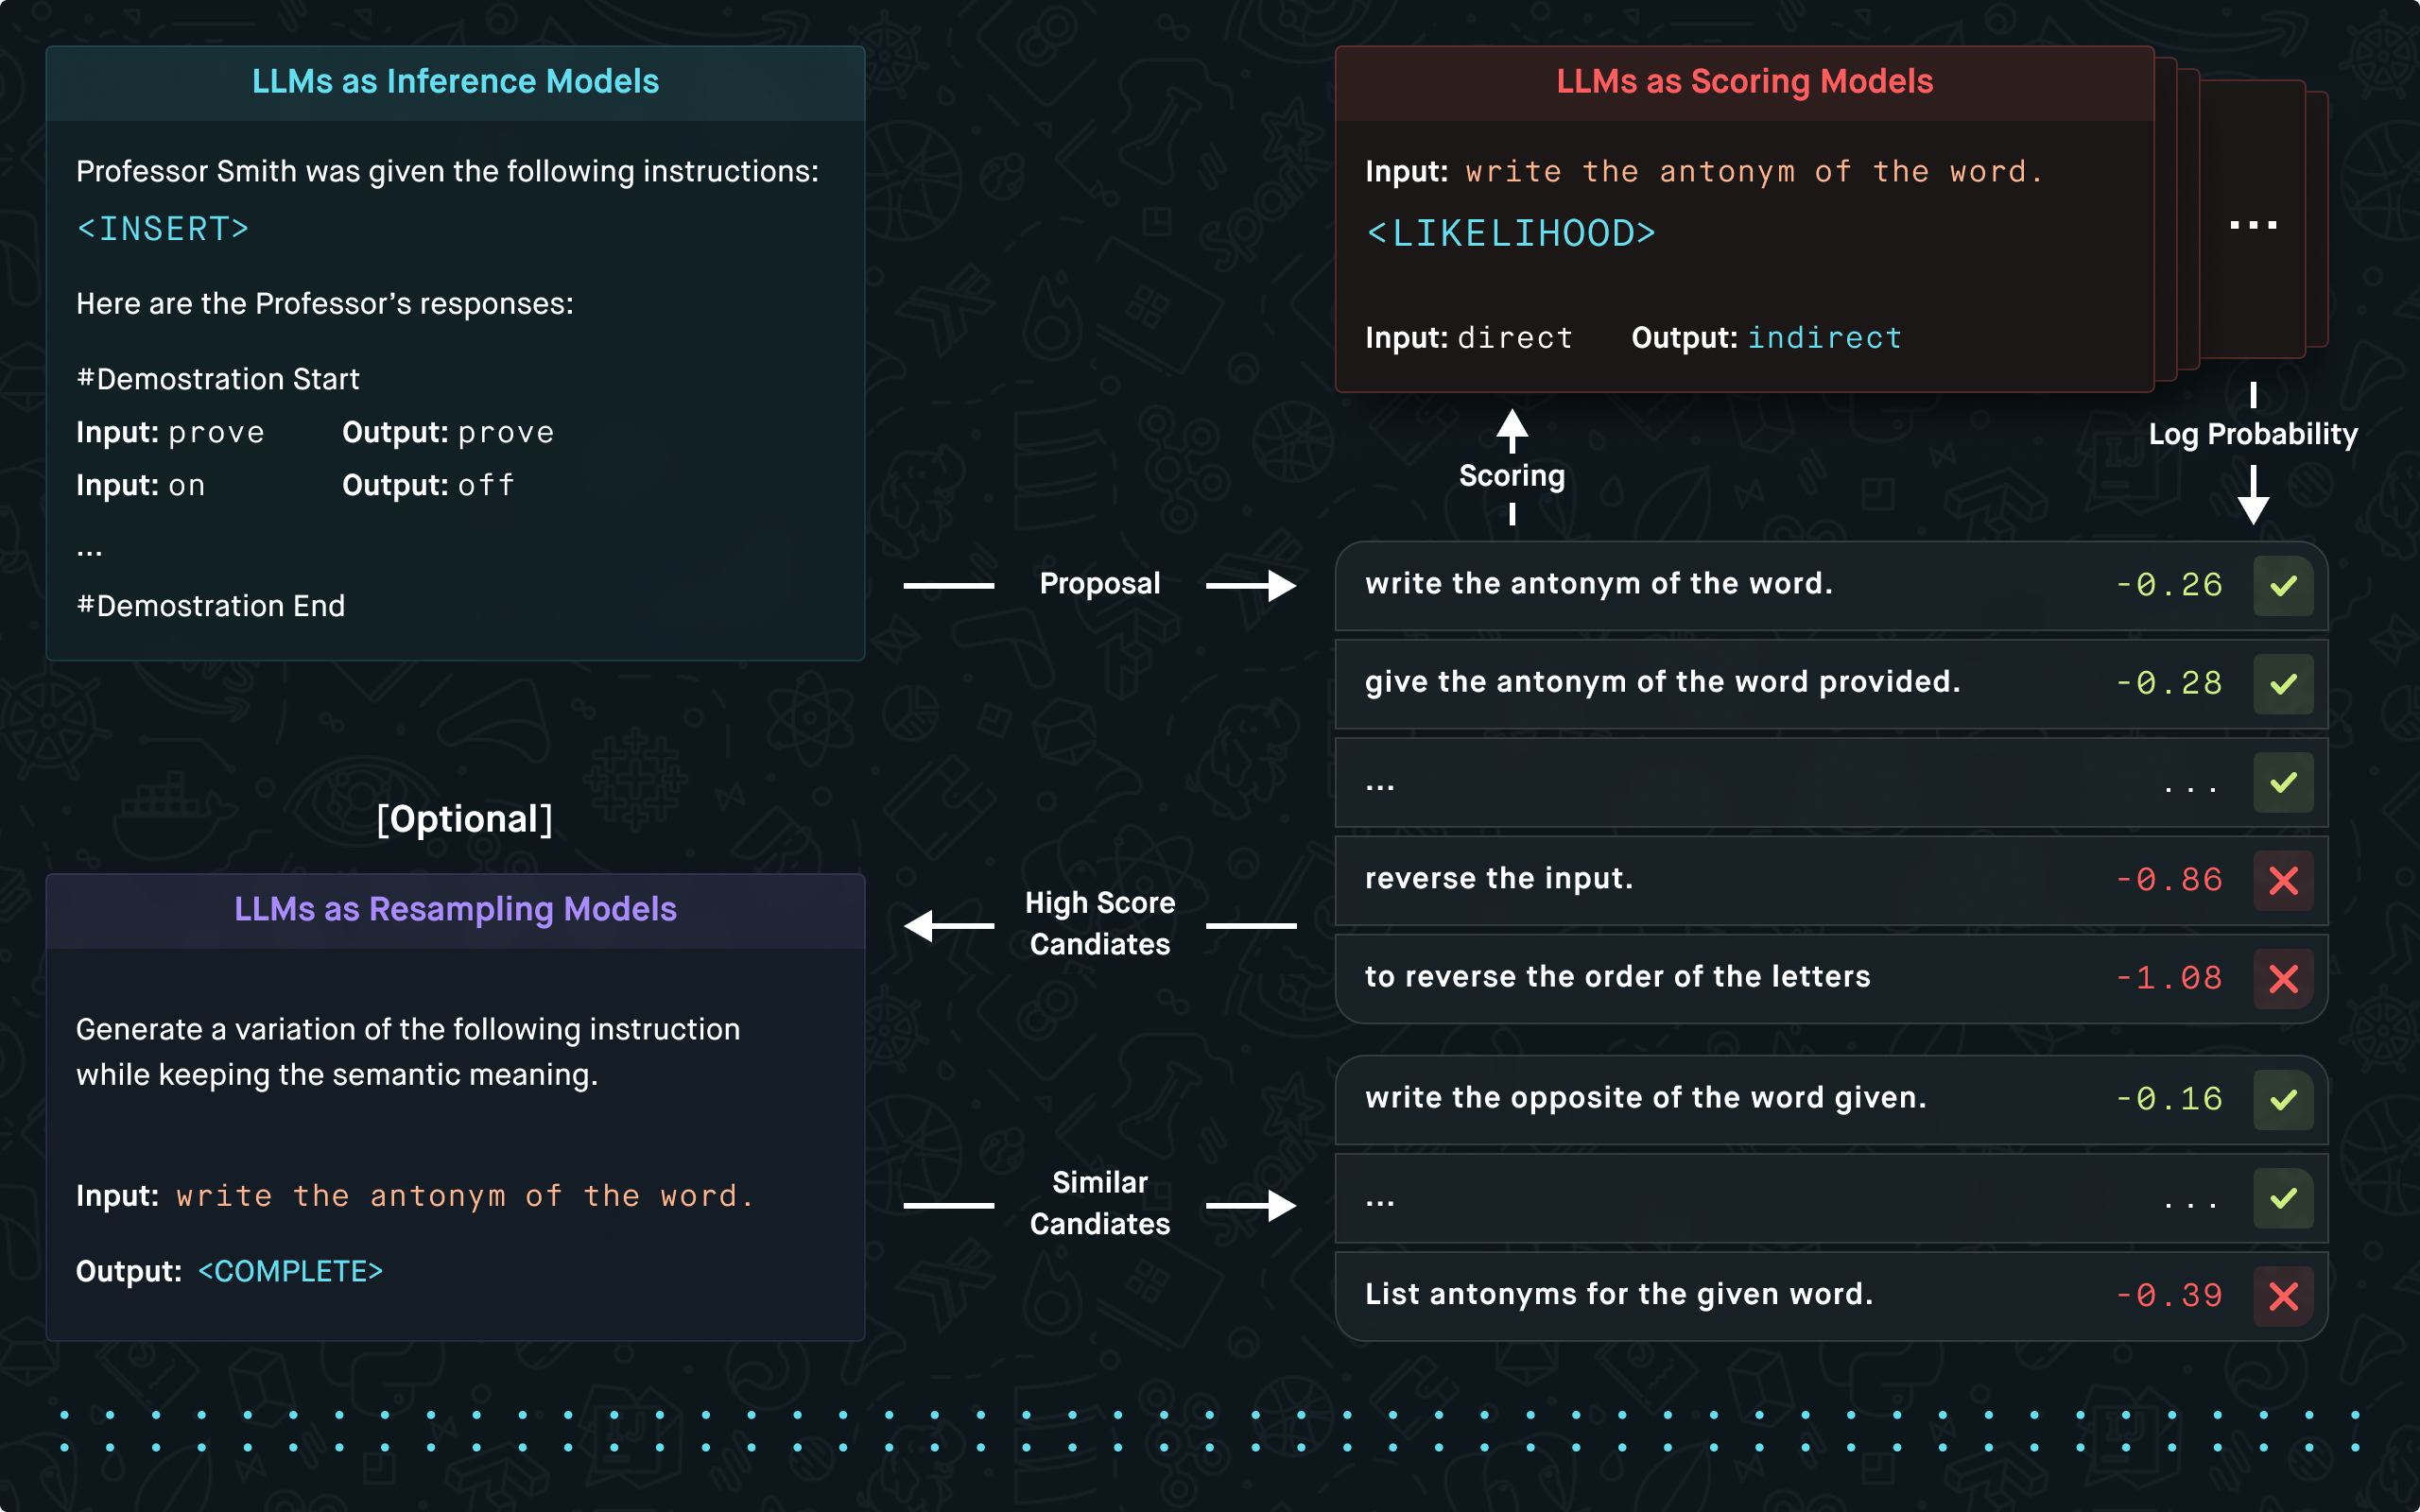
Automatic Prompt Engineer (APE) refers to a system or method that automates the creation of effective prompts for LLMs. Given that the performance of models like GPT-3 or BERT heavily relies on how questions or prompts are structured, APE aims to optimize this aspect, ensuring that interactions are more efficient, accurate, and user-friendly.
APE analyzes the context and the specific requirements of a user's query. It then intelligently formulates a prompt most likely to yield accurate and relevant responses. This process involves understanding the nuances of language, the intent behind the query, and the capabilities of the language model.
For example, suppose a user asks a complex question about a specialized topic. In that case, APE might reformulate this query into a format that more effectively taps into the LLM's extensive database, ensuring that the response is both comprehensive and accurate. Or, if a query is ambiguous, APE might generate multiple prompts that explore different interpretations of the query, thereby covering a broader range of potential responses.
- Context Analysis
APE evaluates the context and specific needs of the user's query. - Prompt Formulation
Based on this analysis, it crafts a prompt that effectively communicates the query to the AI model. - Response Optimization
The prompt is designed to elicit the most accurate and helpful response from the AI, tailored to the user's intent.
Automatic Reasoning And Tool-Use
AUTOMATIC REASONING AND TOOL-USE
Automatic Reasoning and Tool-Use (ART) refers to the ability of LLM systems to not only reason through complex problems but also to utilize external tools or resources to aid in solving these problems. This approach represents a significant leap from traditional AI capabilities, primarily focusing on processing and responding based on pre-existing knowledge or algorithms.
ART involves two key components: Automatic Reasoning and Tool-use.
- Automatic Reasoning
This aspect focuses on the ability to analyze and reason through problems logically, often involving multiple steps or complex scenarios. It is akin to a human's thought process to dissect and understand a problem. - Tool-use
This facet of ART involves actively seeking out and utilizing external tools or resources. These tools could be databases, software applications, or other systems. The choice of tool is determined by its suitability and effectiveness in contributing to the solution.
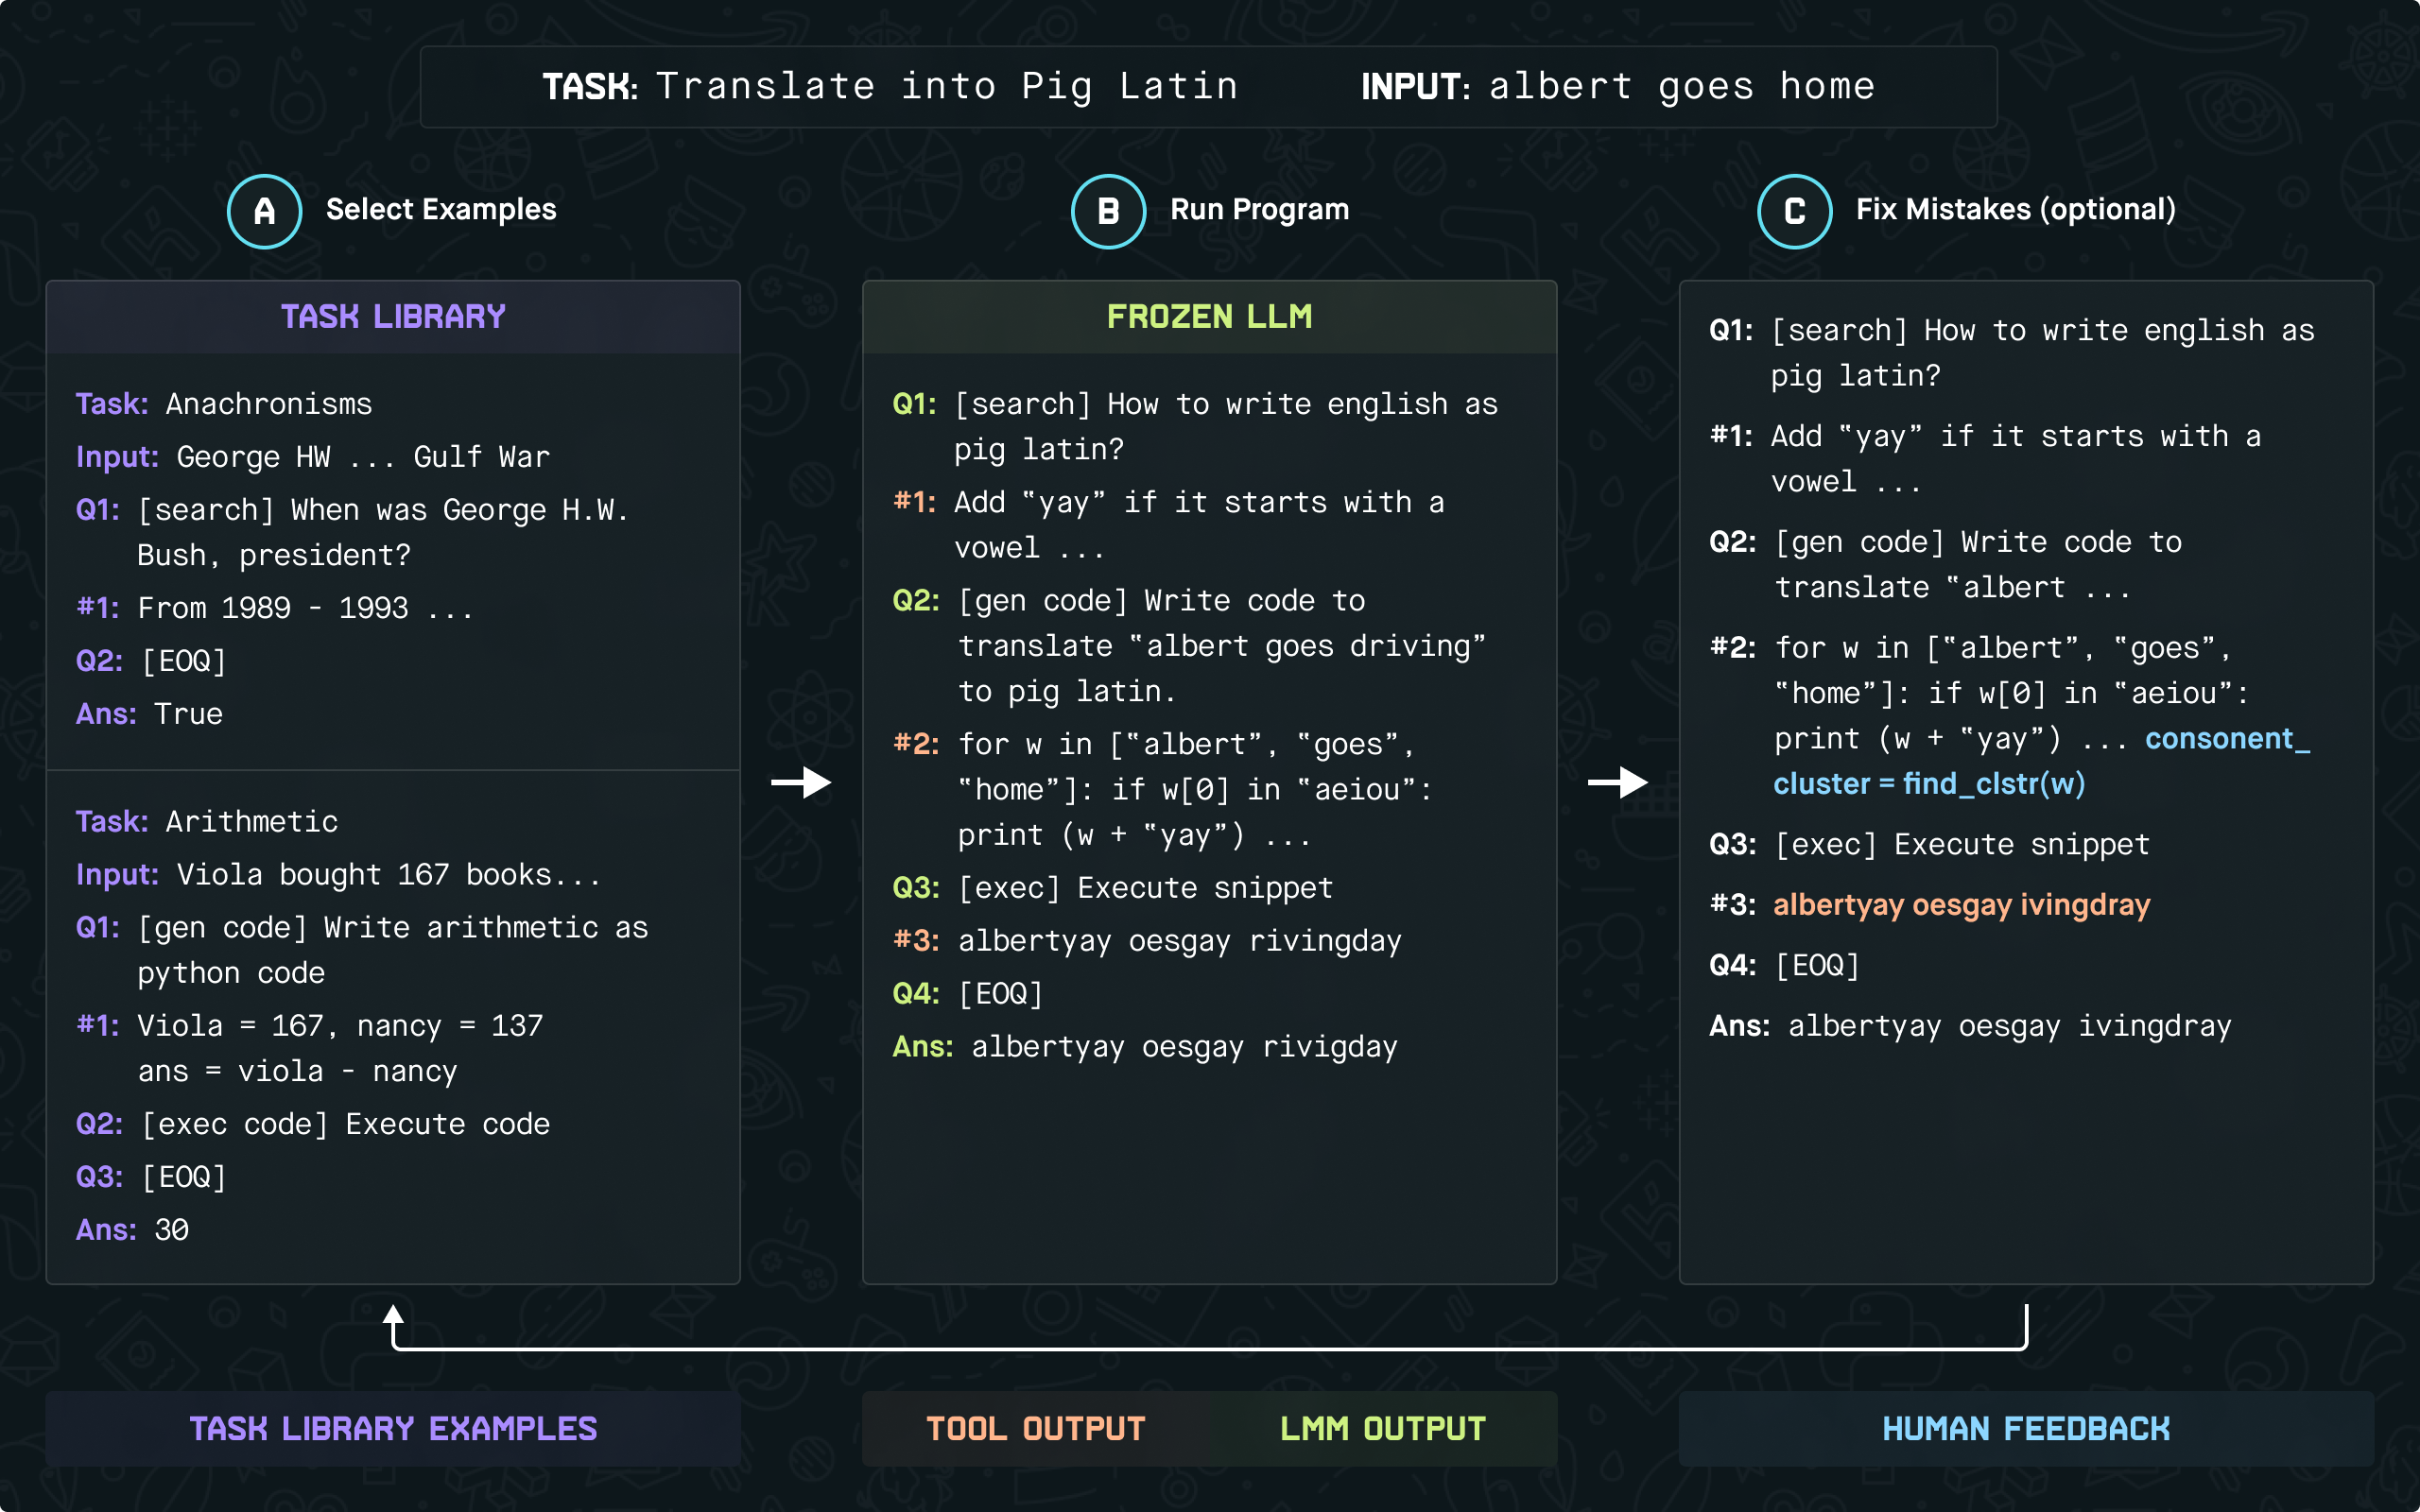
ART prompts the model to apply learnings from demonstrations to break down a new task and appropriately use tools, all in a zero-shot manner. Moreover, ART's extensibility allows humans to correct errors in the reasoning steps or integrate new tools by updating the task and tool libraries.
The process is illustrated as follows:
Active Prompting
ACTIVE PROMPTING
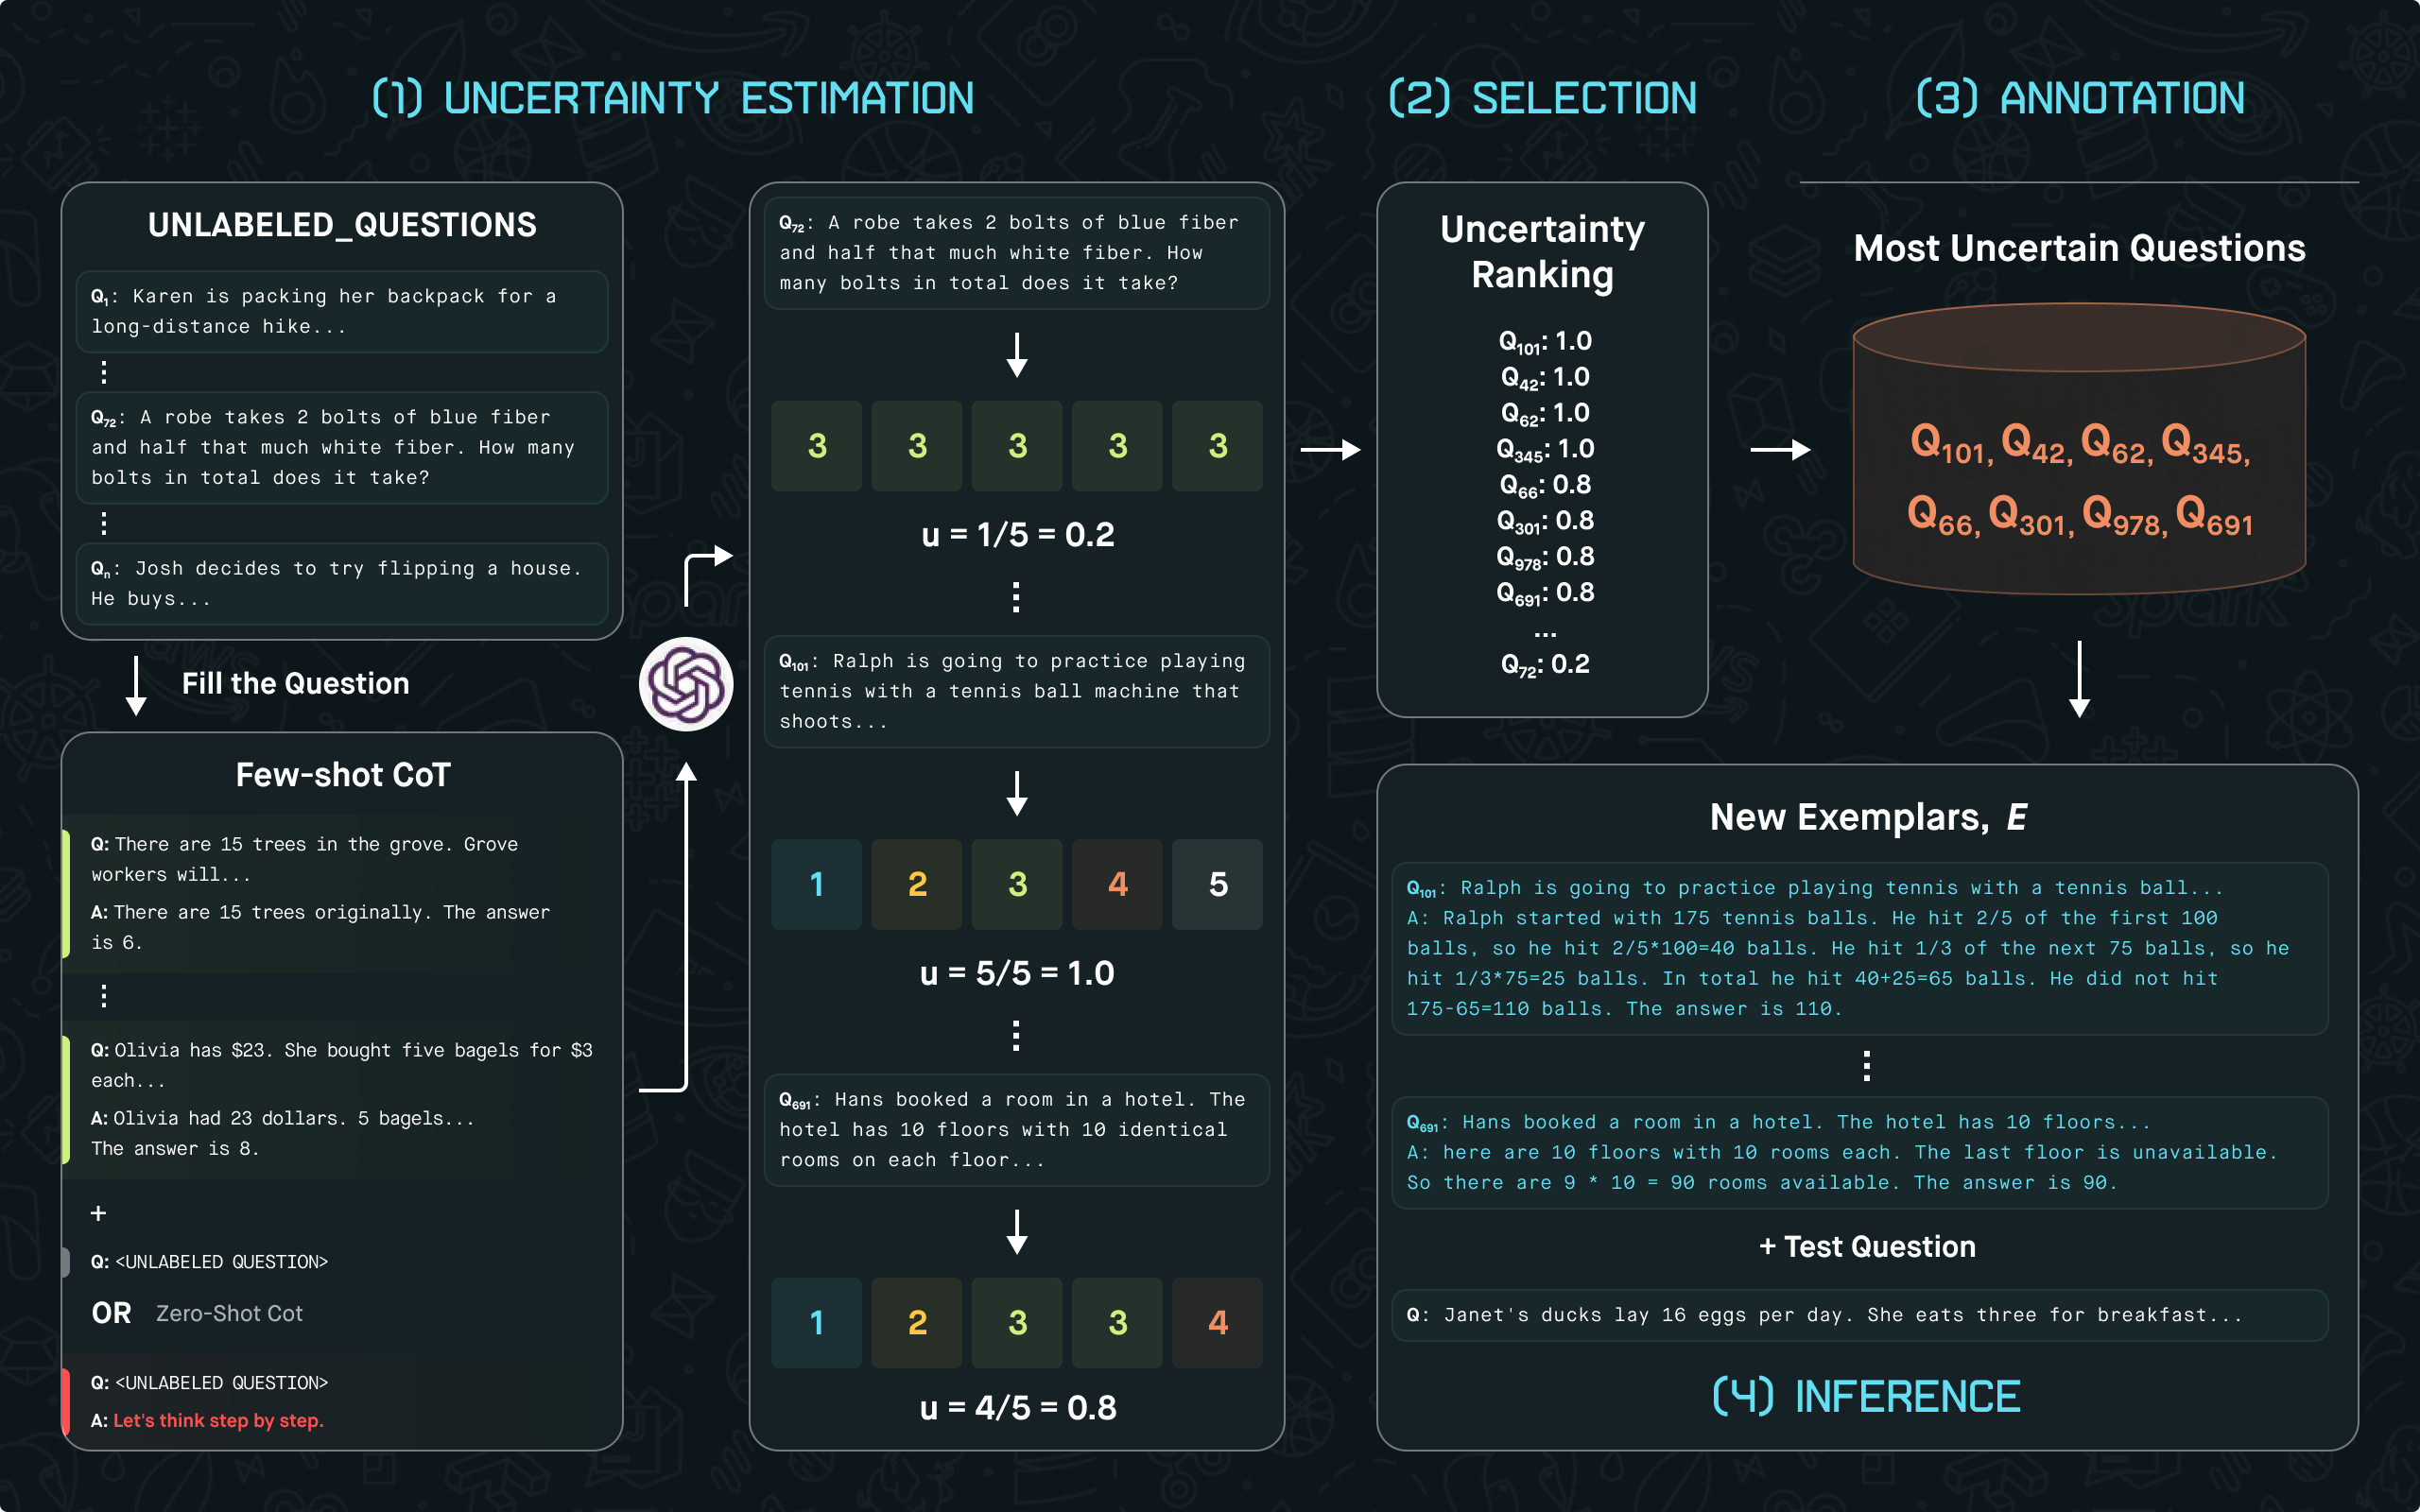
The Active Prompting technique in LLM is a method where prompts are dynamically adjusted or refined in real time based on the ongoing interaction between the user and the language model. This technique is particularly relevant in advanced language models and interactive AI systems. Unlike static prompts, which remain the same regardless of the system response or user input, Active Prompts are responsive and evolve during the interaction.
Active prompt operates on the principle of continuous feedback and adjustment. The model not only processes the initial prompt but also considers the responses and further inputs from the user, adjusting subsequent prompts accordingly. This creates a more fluid and context-aware interaction.
- Initial Prompt and Response
The interaction begins with a user issuing a prompt and the LLM model responding. - Feedback Loop
The user's follow-up actions or responses serve as feedback. - Prompt Adjustment
Based on this feedback, the LLM model actively adjusts the following prompt or its approach to the problem.
Multimodal Chain-of-Thought Prompting
MULTIMODAL CHAIN-OF-THOUGHT PROMPTING
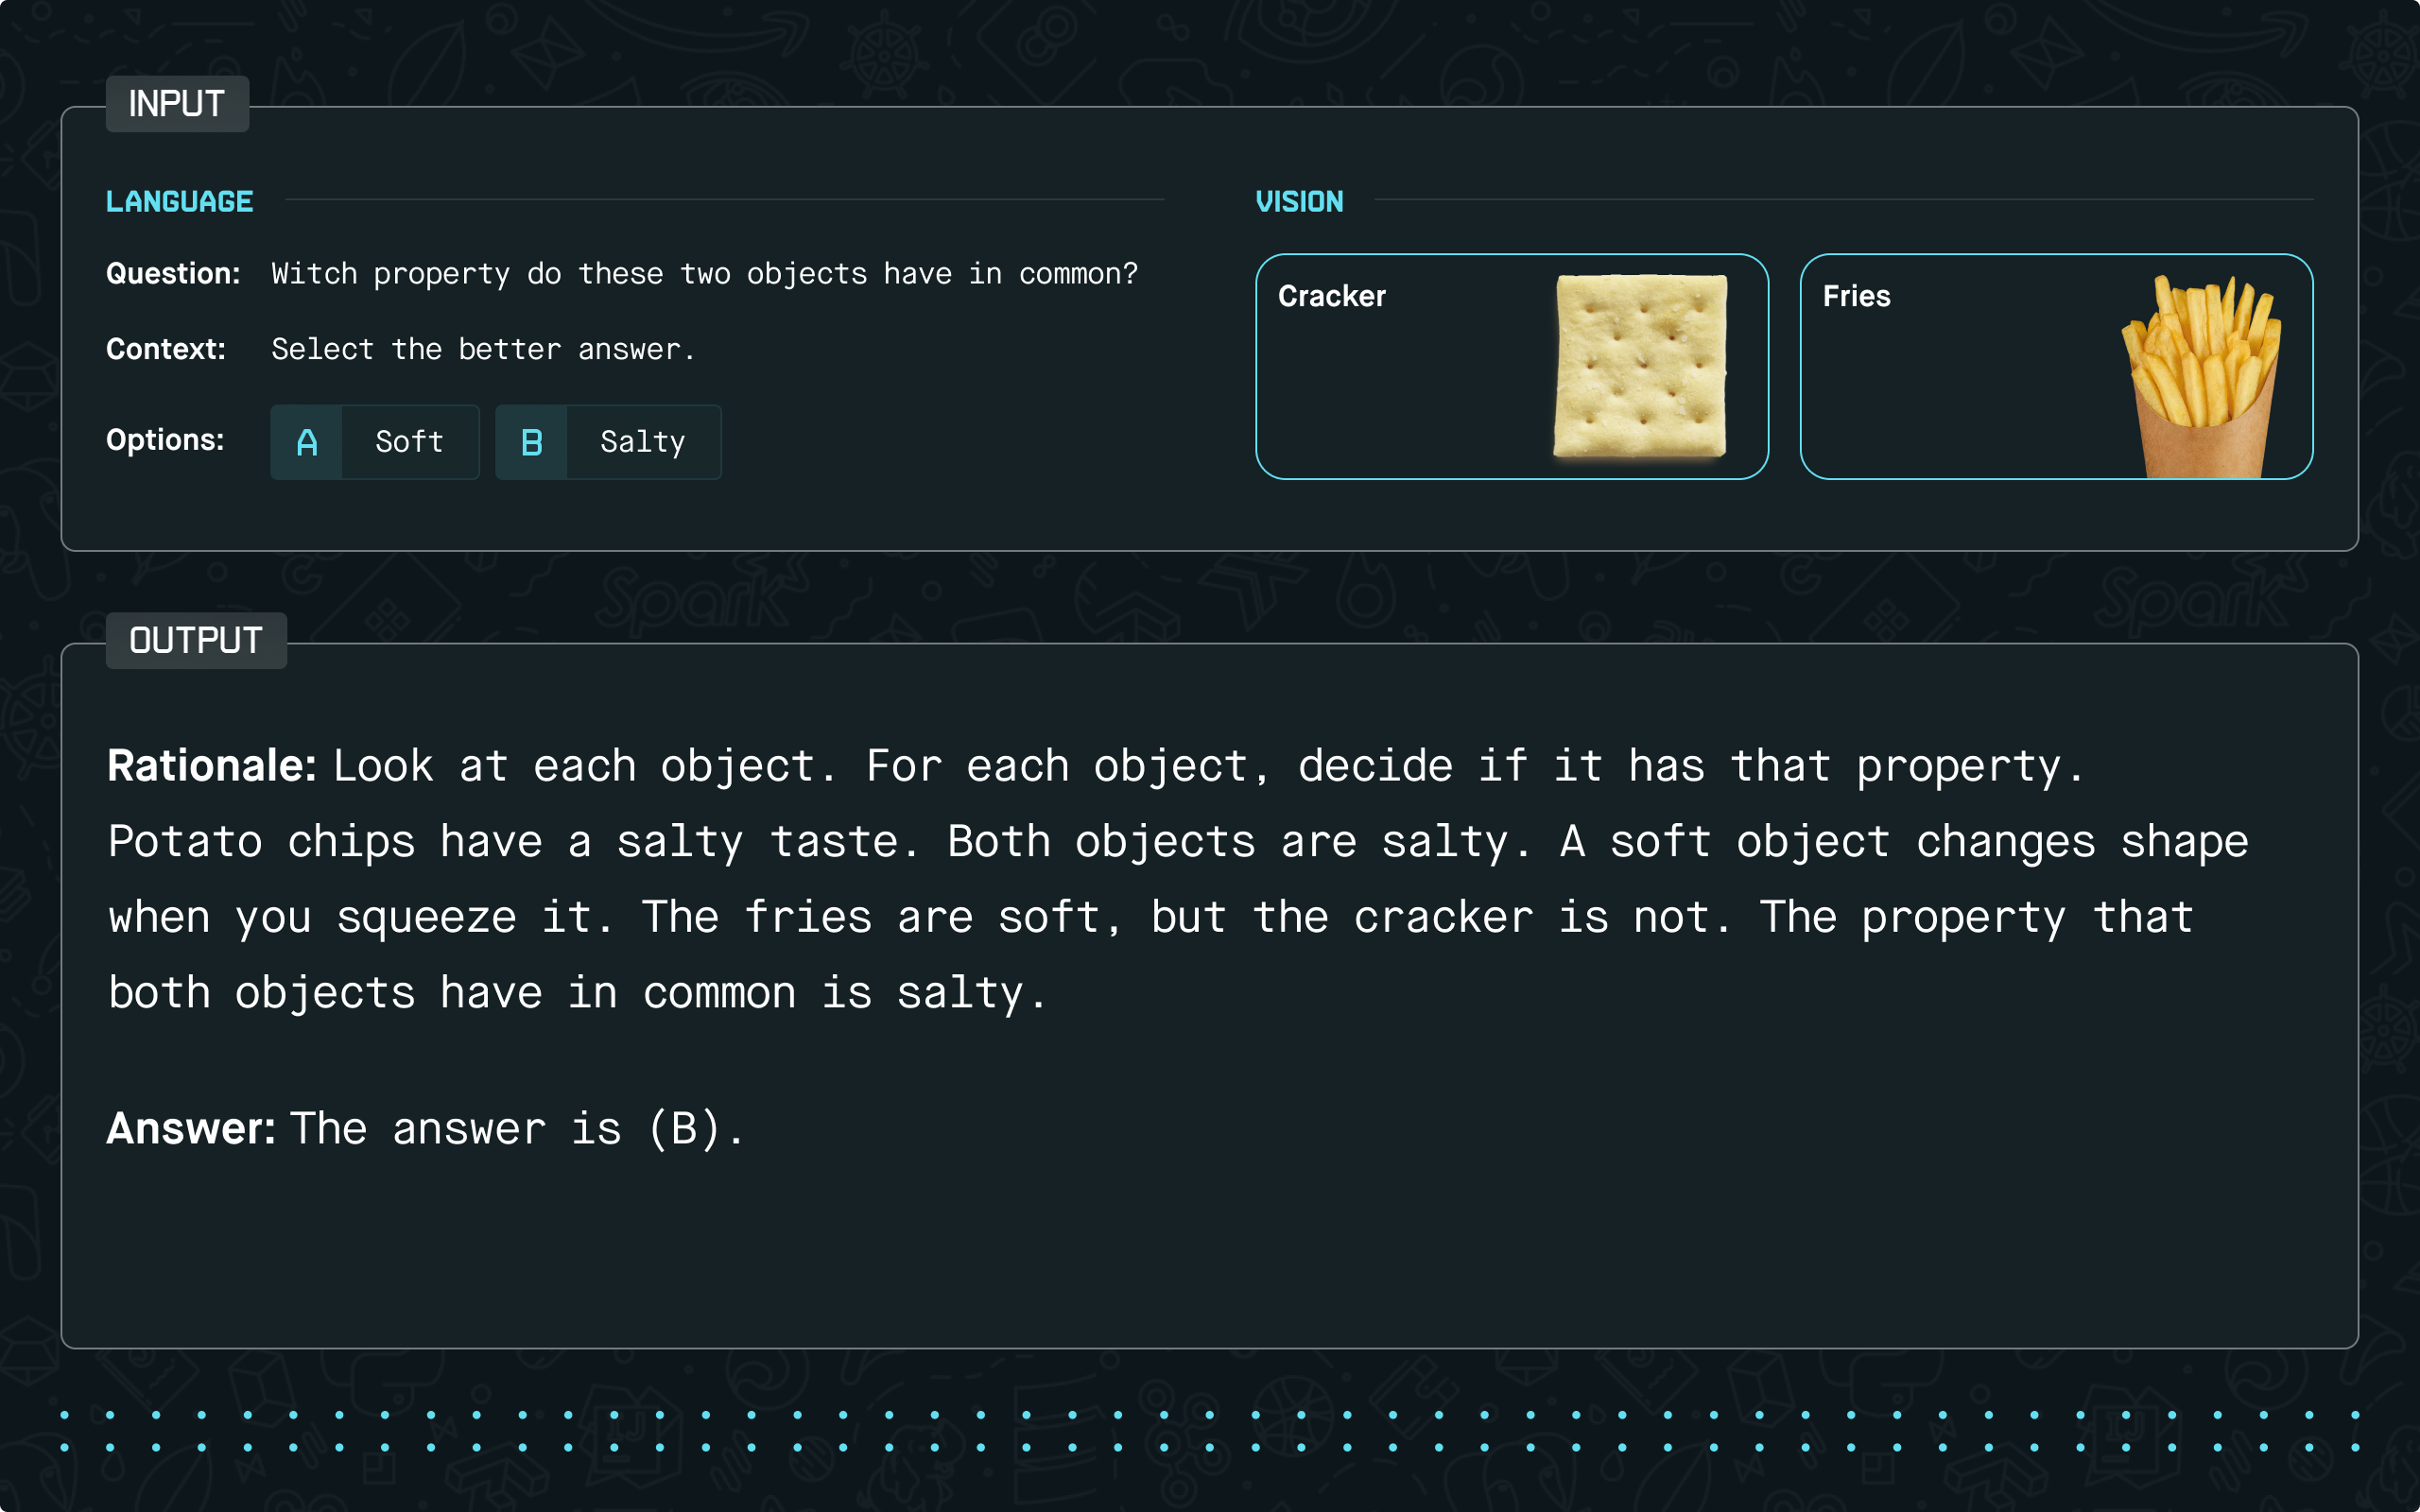
Multimodal Chain-of-Thought Prompting is an advanced technique that integrates various data modalities, such as language (text) and vision (images), into the reasoning process. This approach enhances large language models by enabling them to generate more comprehensive rationales based on multimodal information before inferring answers.
It operates in a two-stage framework: first, it generates rationales using text and images and then leverages these multimodal rationales to infer answers. This method allows for more prosperous, more accurate problem-solving capabilities in LLMs.
Directional Stimulus Prompting
DIRECTIONAL STIMULUS PROMPTING
Directional Stimulus Prompting employs a tunable language model to guide a black-box, fixed large language model toward desired outcomes. The process involves training a policy LM to create specific tokens that serve as directional cues for each input. These cues function like keywords in an article for summarization, providing hints or guidance. The directional stimulus, once created, is merged with the original input and inputted into the LLM. This method helps steer the LLM’s generation process toward the targeted objective.
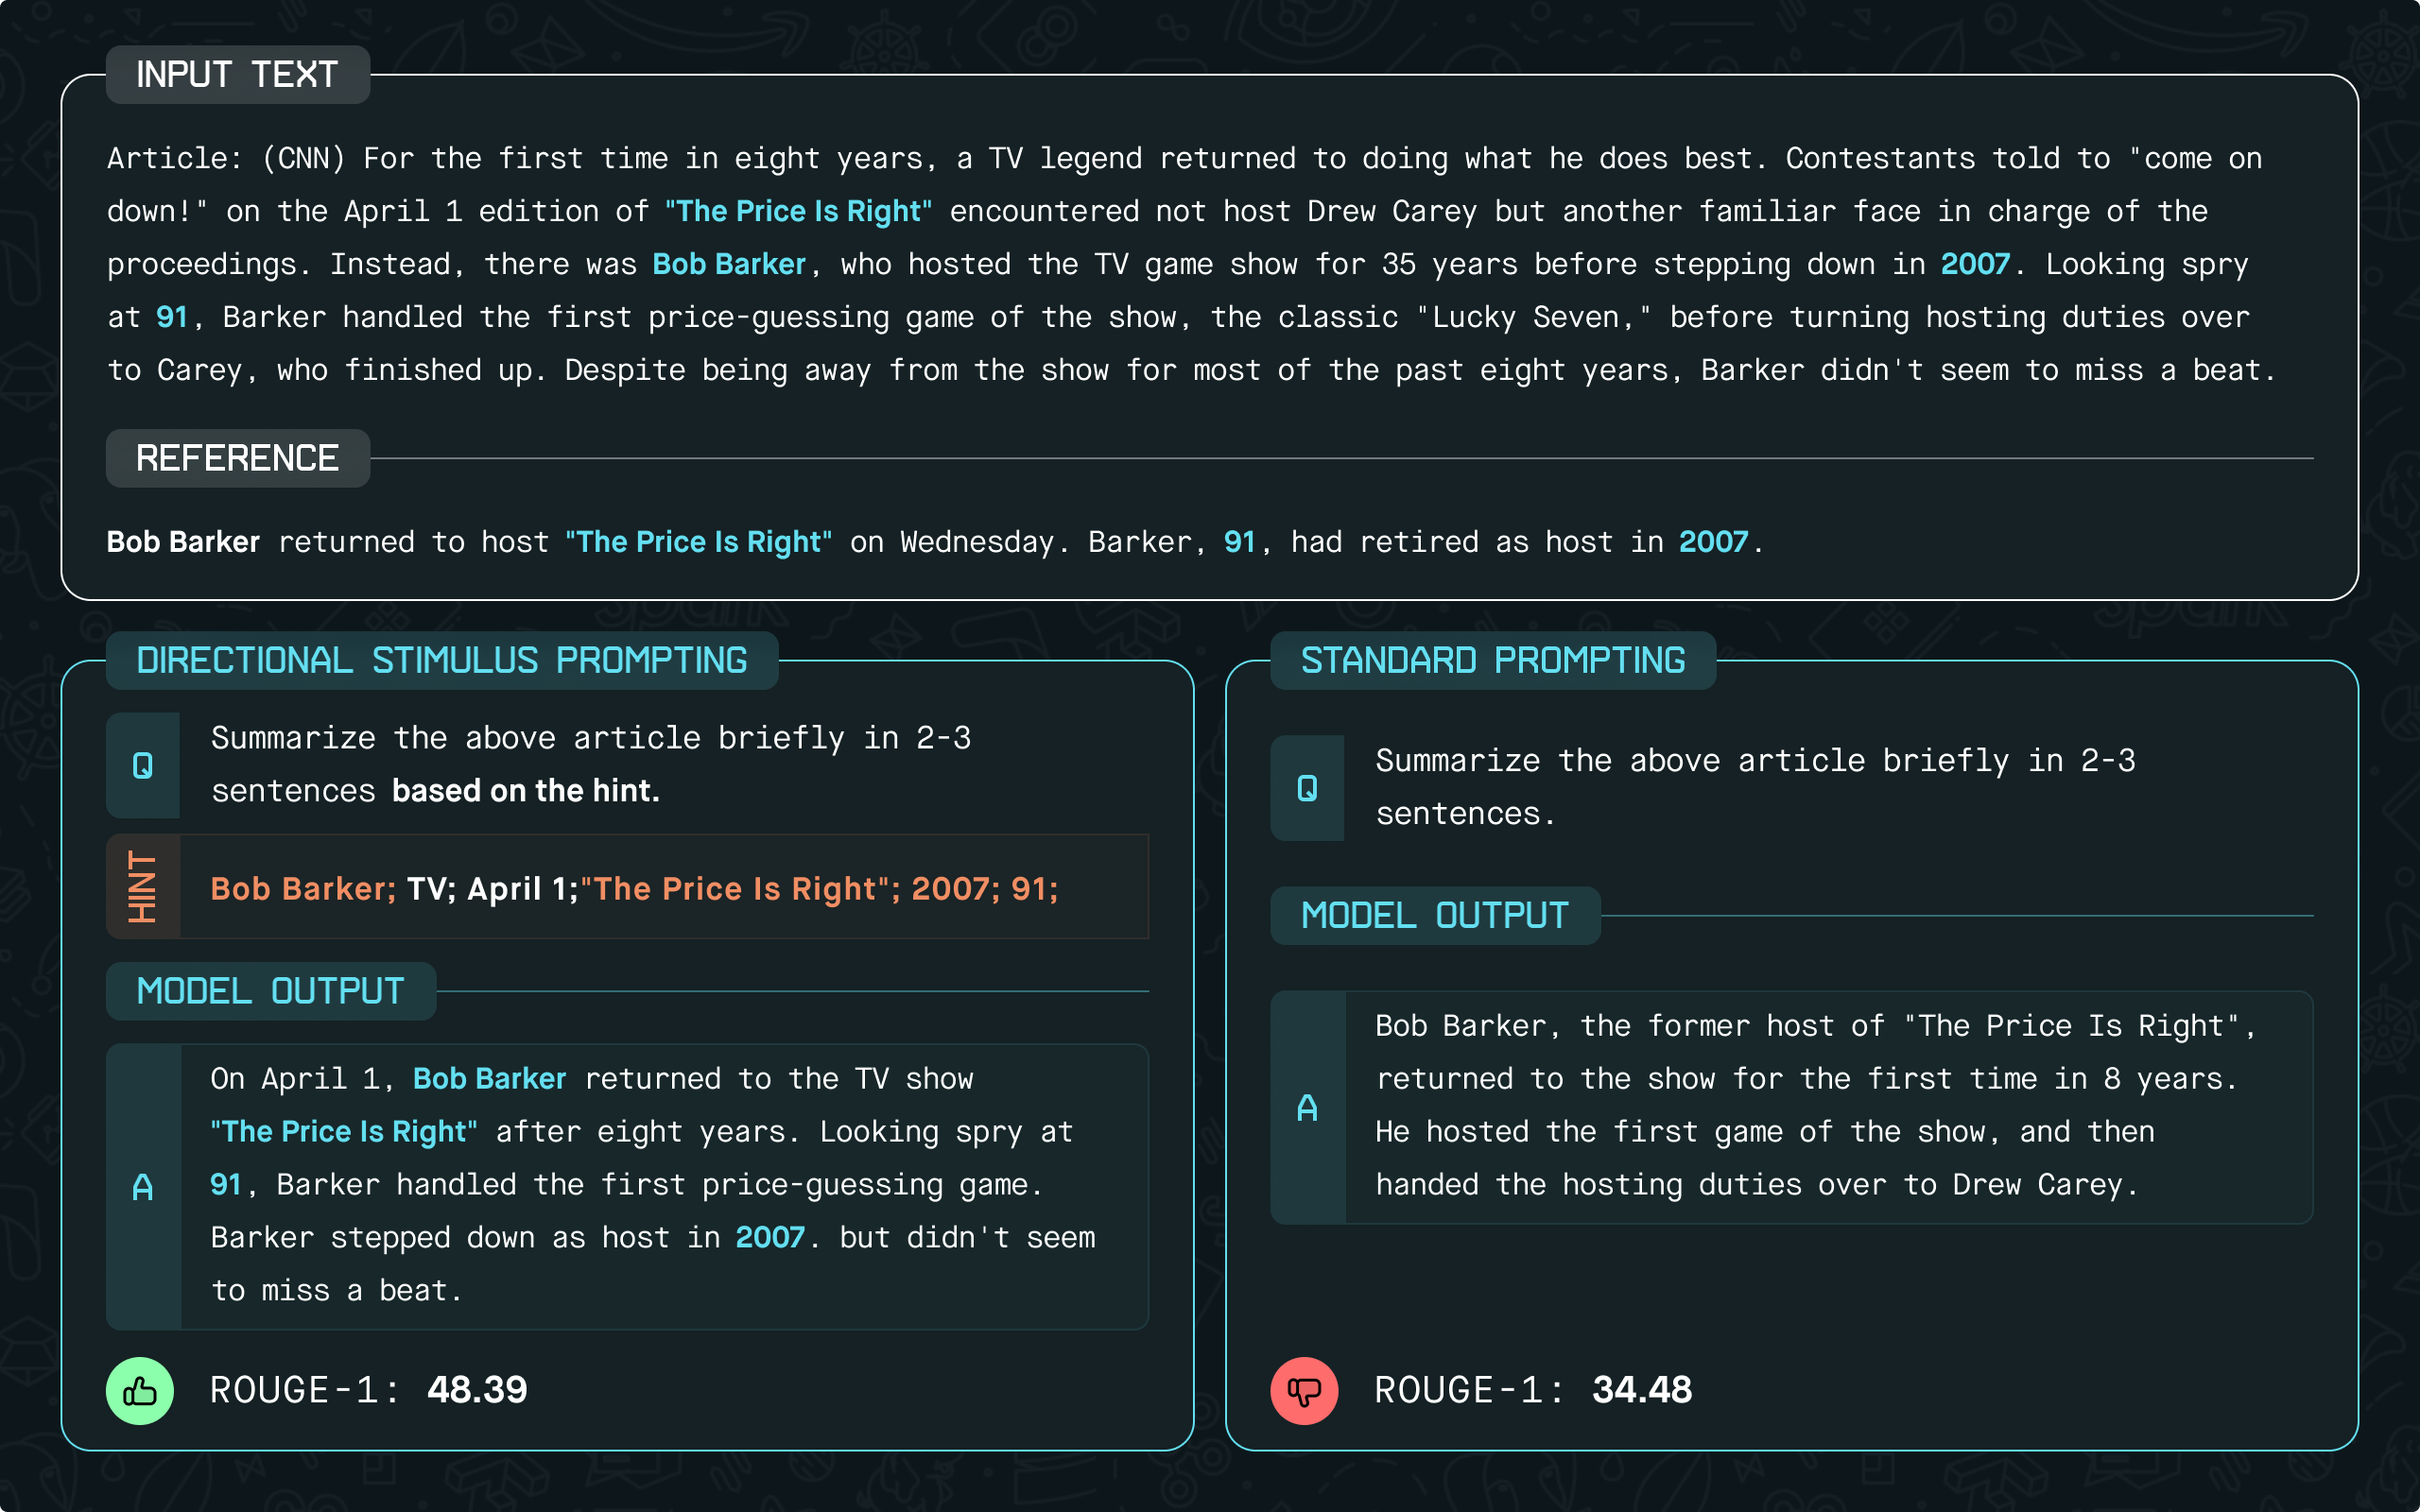
How DSP Works:
- Stimulus Generation
A tiny LM called a policy LM, is trained to generate a series of discrete tokens as a directed stimulus. These tokens provide specific information or instructions related to the input sample rather than being a generic cue. - Integration with LLMs
The created stimulus is combined with the original input and fed into the LLM. This process steers the LLM’s output generation towards the desired goal, such as better performance scores. - Training methodology
Initially, supervised fine-tuning (SFT) is employed with a pre-trained LM using a limited number of training samples. The goal is to maximize the reward, defined by the performance measures of the LLM’s output based on the stimulus produced by the policy LM. Following this, reinforcement learning (RL) is used for further optimization to discover more effective stimuli.
ReAct
REACT PROMPTING
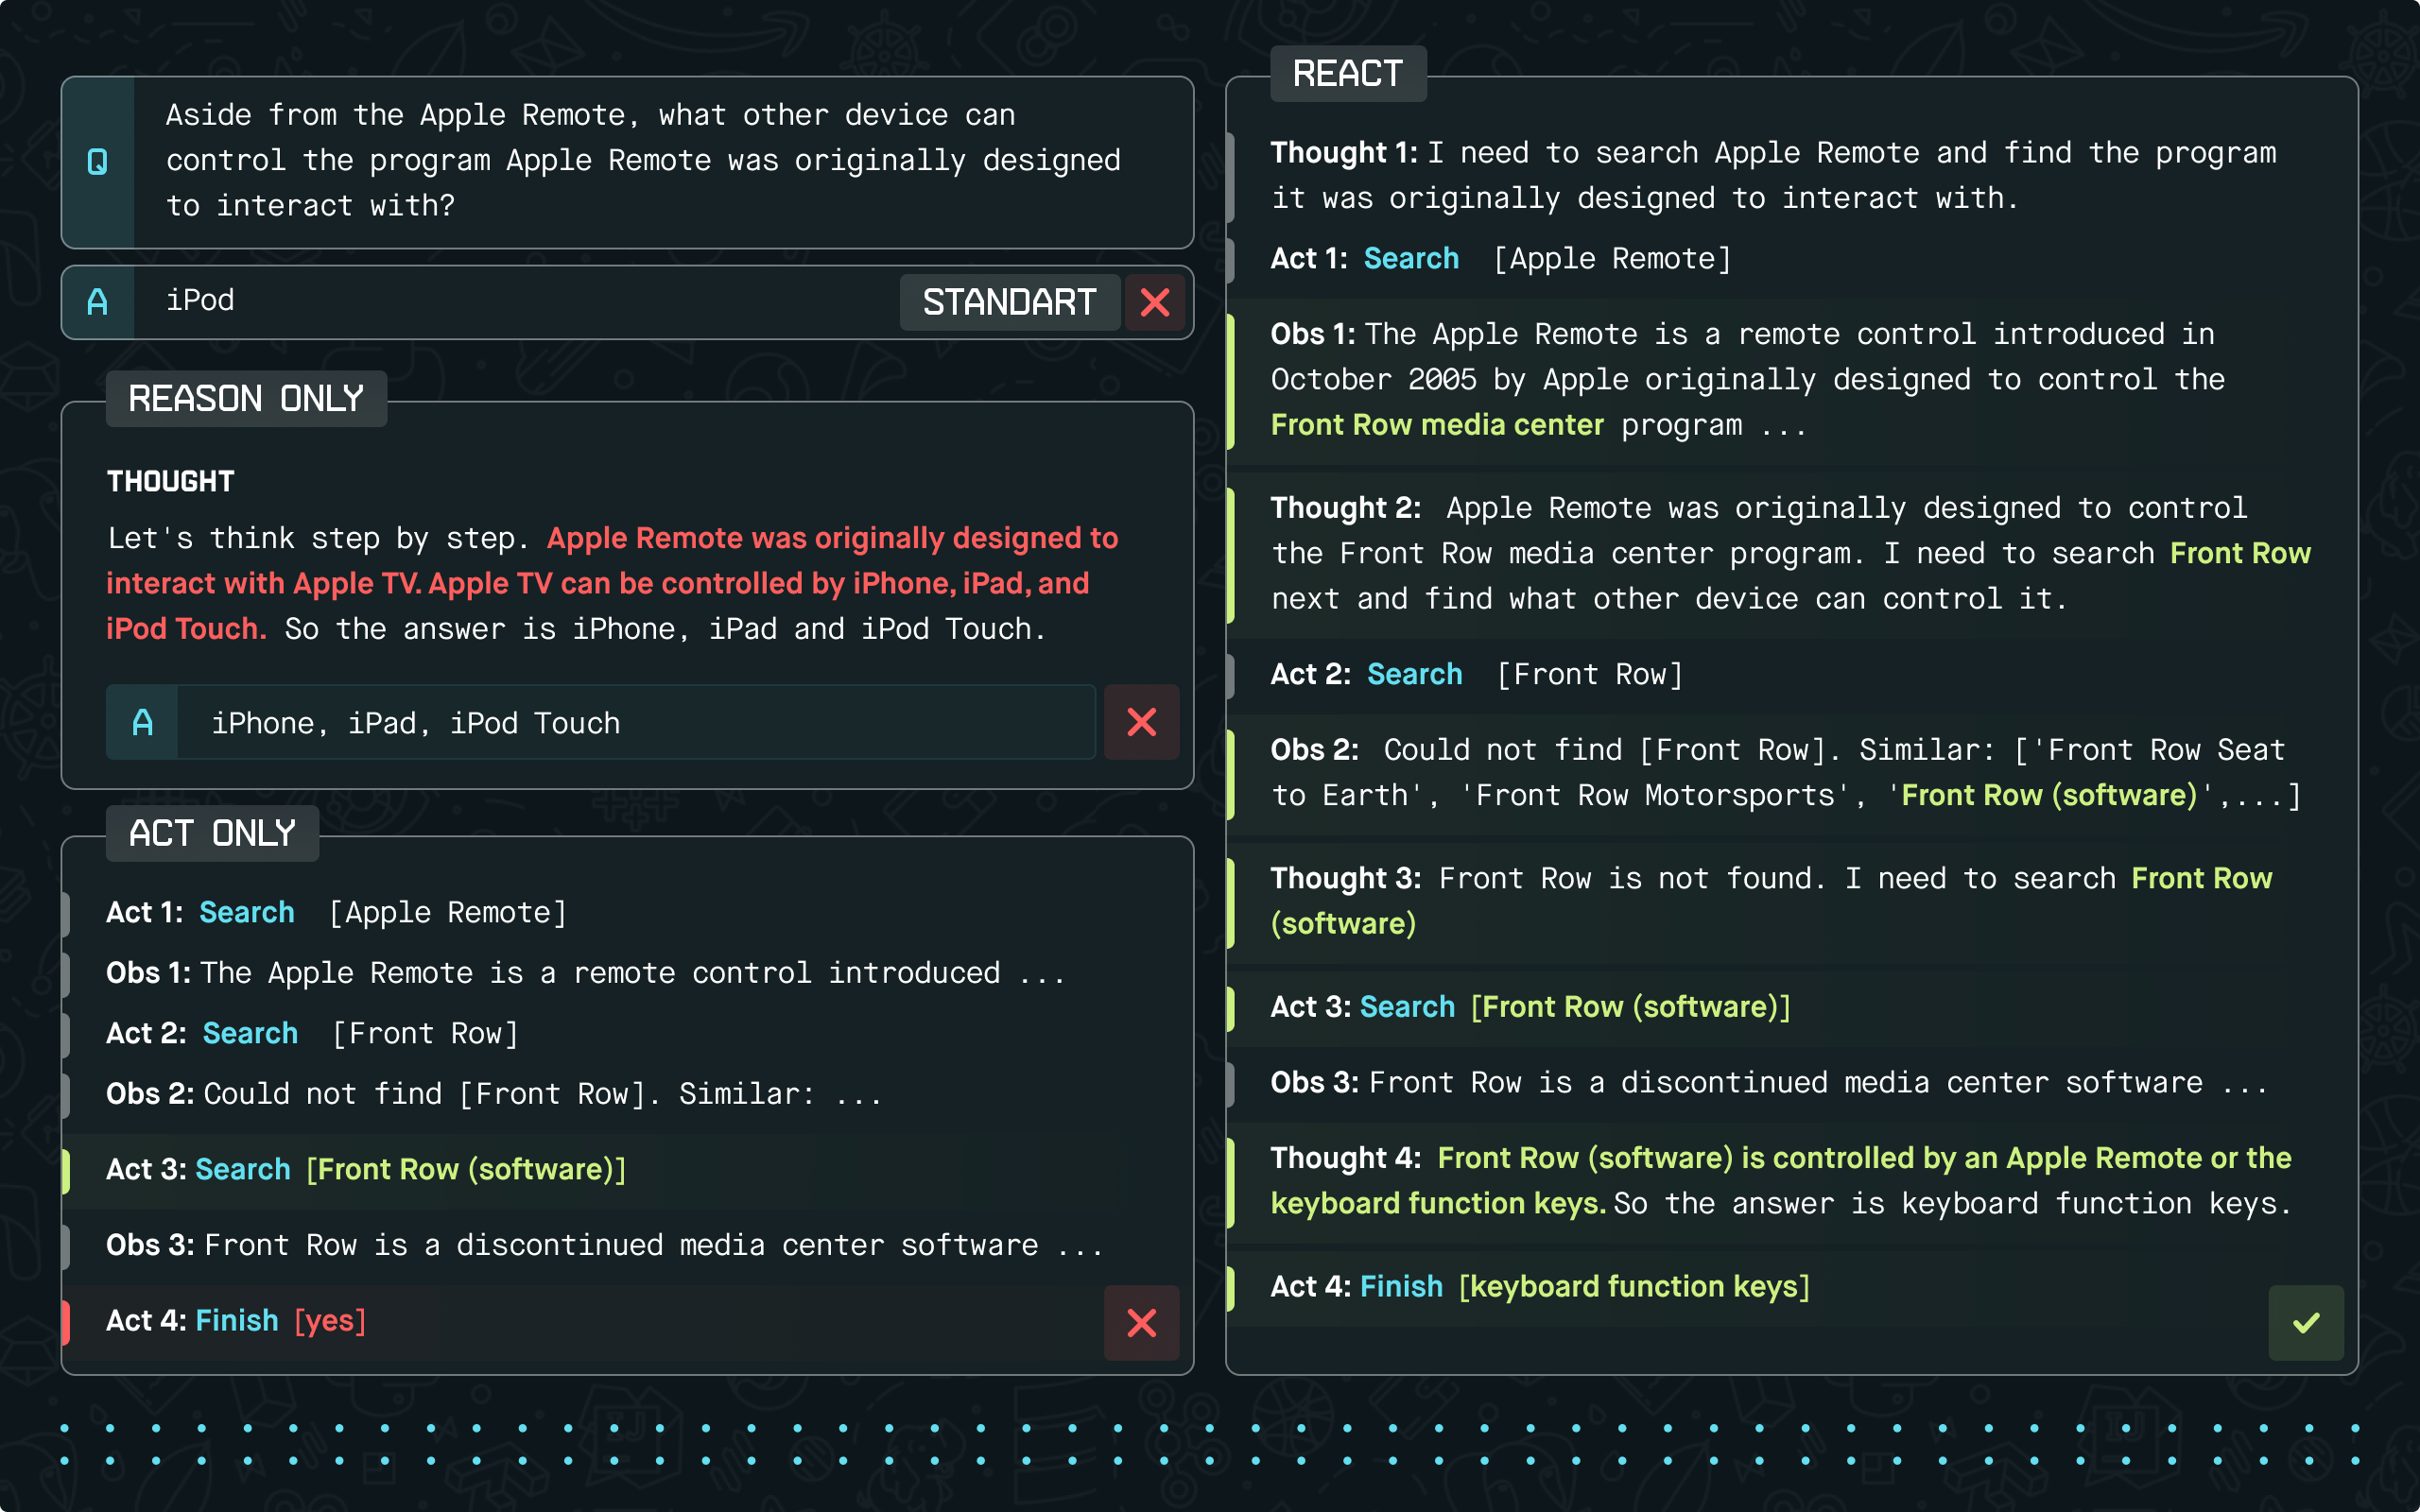
ReAct prompting, created by Yao and colleagues in 2022, is a technique designed to improve LLMs like GPT-3 and GPT-4. It goes beyond traditional methods such as chain-of-thought (CoT) by integrating reasoning, action planning, and using external knowledge sources. The main goal of ReAct, short for "Reasoning and Acting," is to enhance the accuracy of LLMs' responses. This is achieved by a distinctive approach that combines complex reasoning processes with the ability to plan actions and incorporate diverse knowledge sources. This method allows them to go beyond their intrinsic language abilities, incorporating real-world information into their outputs for more accurate and contextually relevant responses.
- HotpotQA Example:
The chain-of-thought baseline struggles with misinformation due to its reliance on limited internal knowledge, while the action-only baseline lacks reasoning capabilities. ReAct, however, successfully combines reasoning with factual accuracy to solve the task effectively.
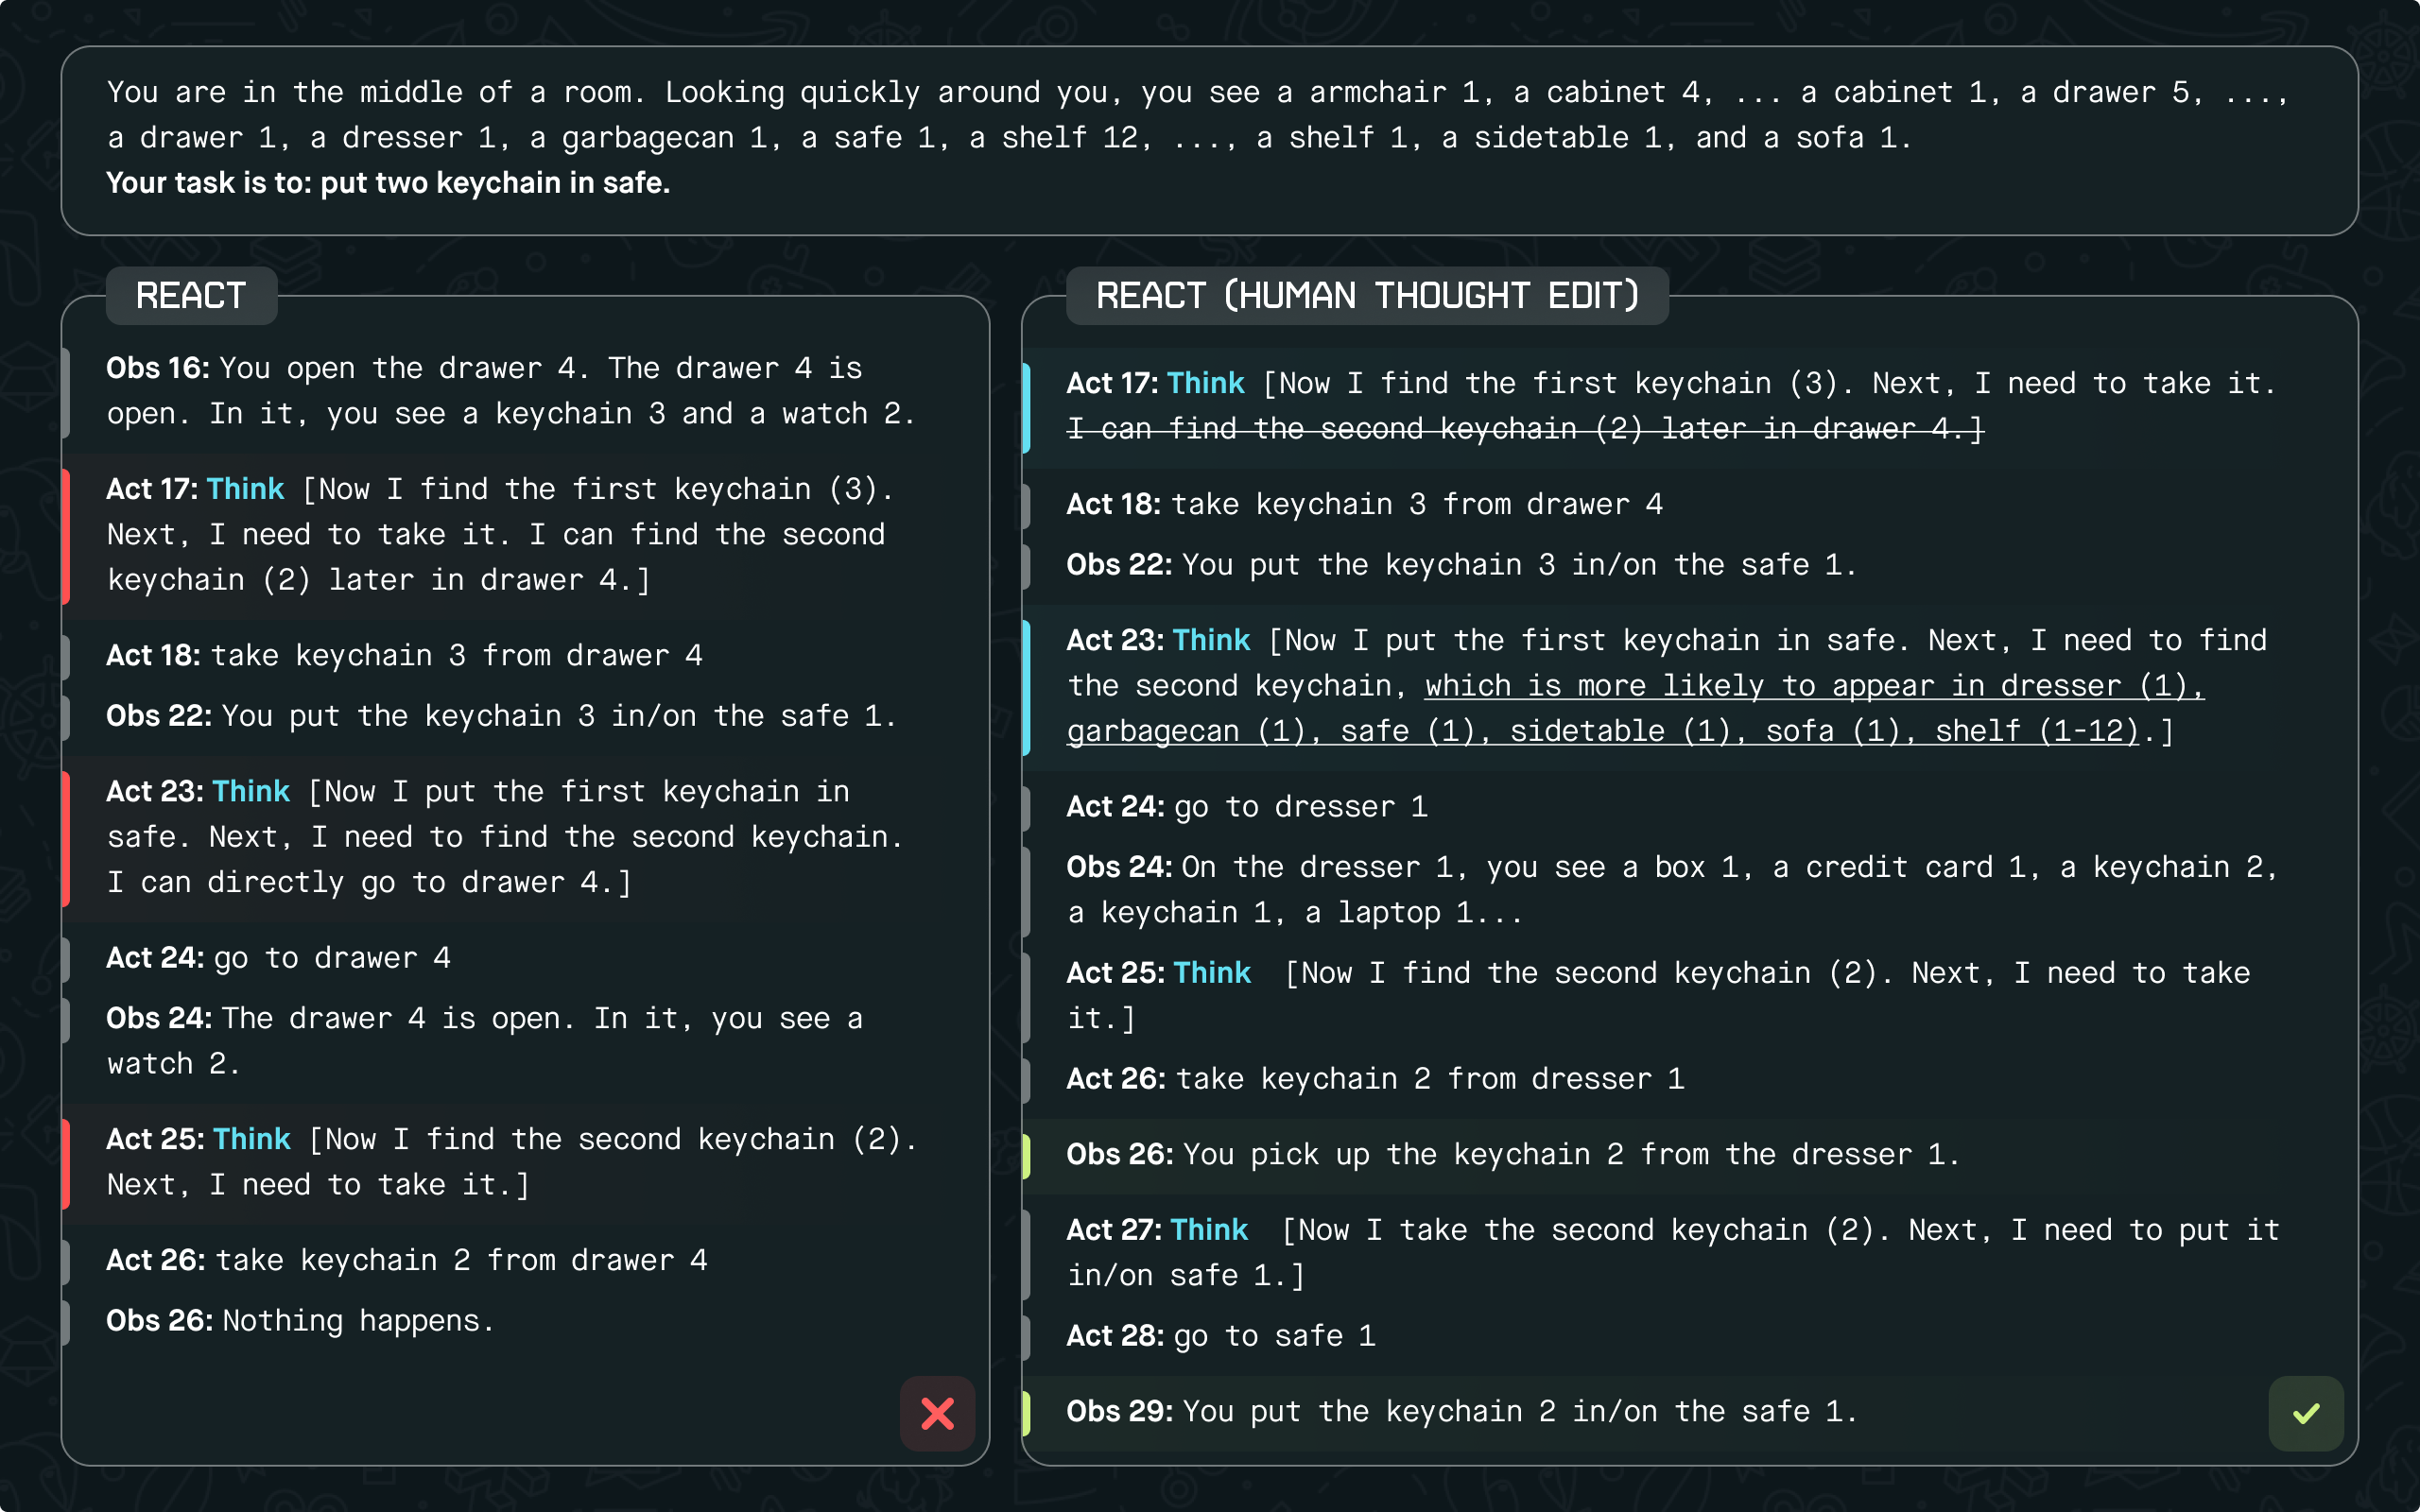
- ALFWorld Example:
In decision-making tasks, we create human trajectories with minimal reasoning traces, allowing the language model to balance thinking and acting. ReAct has its flaws, as seen in an ALFWorld failure example. Yet, its format facilitates straightforward human review and correction by modifying a few model thoughts, offering a promising new method for aligning with human intent!
For a detailed example of how the ReAct prompting approach works in practice, see LangChain Example.
Tools to Enhance LLM Prompting
In the ever-evolving landscape of large language models, prompting tools have emerged as a cornerstone for harnessing their full potential. These tools enable users, from seasoned programmers to novices, to interact with large language models in a way that is both intuitive and powerful.
WHAT ARE PROMPTING TOOLS?
Prompting tools are interfaces or platforms that allow users to communicate with models through prompts - instructions, or requests written in natural language. These tools bridge the user's intent and the models' capabilities, translating human language into tasks that can be understood and executed.
TYPES OF PROMPTING TOOLS
- Text-based tools
These tools interact primarily through text, such as chatbots or text generators. They are widely used for content creation, customer service, and educational purposes. - Code-focused tools
For those in the programming field, like Python developers, code-focused prompting tools can assist in debugging, writing code, or even explaining complex algorithms in simpler terms. - Visual tools
These tools can generate or modify images and videos based on textual or visual prompts, widely used in creative industries like design and marketing.
We will focus on code-focused tools and review a few of the most exciting and effective.
GUIDANCE
The guidance library in Python is a novel programming paradigm designed for controlling large language models (LLMs) with enhanced control and efficiency. Unlike traditional prompting and chaining methods, the guidance allows for the seamless integration of generation constraints (like regular expressions and context-free grammars) with control structures (like conditionals and loops). Here are some key features and examples of how guidance can be used:
Basic Generation with Python. The guidance leverages Python's clarity and additional LLM functionalities. For instance, you can load a model like LlamaCpp and append text or generations to it:
from guidance import models, gen


llama2 = models.LlamaCpp(path)
llama2 + f'Do you want a joke or a poem? ' + gen(stop='.')
Constrained Generation. The library supports constrained generation using select, regular expressions, and context-free grammars. For example:
from guidance import select


llama2 + f'Do you want a joke or a poem? A ' + select(['joke', 'poem'])
Stateful Control and Generation. The guidance facilitates the interleaving of prompting, logic, and generation without needing intermediate parsers:
# capture our selection under the name 'answer'
lm = llama2 + f"Do you want a joke or a poem? A {select(['joke', 'poem'], name='answer')}.\n"
# make a choice based on the model's previous selection
if lm["answer"] == "joke":
    lm += f"Here is a one-line joke about cats: " + gen('output', stop='\n')
else:
    lm += f"Here is a one-line poem about dogs: " + gen('output', stop='\n')
See the guidance library documentation for a more detailed look at the capabilities.
LANGCHAIN
LangChain is a comprehensive framework designed to create applications powered by language models. It's tailored to build context-aware and reasoning-based applications, integrating various components into a cohesive system.
LangChain for Prompt Creation:
-
Modular Components
LangChain's architecture is based on modular components. This design allows for the assembly of different parts to create complex prompts. You can start with essential components and gradually add more sophisticated elements to your prompts. -
Prompt Templates
A crucial feature of LangChain is itsPromptTemplateclass. This allows you to create dynamic prompts using templates. For example, you can design a template for generating company names based on product descriptions. This feature is instrumental in constructing prompts that provide contextual information to the language model.
from langchain.prompts import PromptTemplate


prompt = PromptTemplate.from_template("What is a good name for a company that makes {product}?")
prompt.format(product="colorful socks")
# Output: "What is a good name for a company that makes colorful socks?"
- Chat Models and Prompt Templates
LangChain also supports chat models, where prompts are created as a conversation. This is particularly useful for applications like chatbots. You can define the role of each message (e.g., system, human) and format it accordingly.
from langchain.prompts.chat import ChatPromptTemplate


chat_prompt = ChatPromptTemplate.from_messages([
    ("system", "You are a helpful assistant that translates {input_language} to {output_language}."),
    ("human", "{text}")
])
chat_prompt.format_messages(input_language="English", output_language="French", text="I love programming.")
Utilizing Prompts with LangChain:
-
Interaction with Language Models
LangChain provides interfaces to interact with various language models. This interaction is not limited to generating responses but also involves reasoning and decision-making based on the provided prompts. -
Building Chains
You can build chains that combine prompt templates, language models, and output parsers. This approach helps create applications that process user input, generate responses based on prompts, and then parse these responses into a usable format.
from langchain.chat_models import ChatOpenAI
from langchain.schema import BaseOutputParser


# Chain combining a prompt template, chat model, and output parser
chain = chat_prompt | ChatOpenAI() | CommaSeparatedListOutputParser()
chain.invoke({"text": "colors"})
OUTLINES
Outlines, a Python library, enhances text generation with LLMs. It offers an advanced alternative to the transformers library's generate method, with features like robust prompting, regex-guided generation, and JSON schema creation. This tool streamlines prompt creation for LLMs, replacing complex string concatenation in Python with straightforward and efficient prompting primitives using the Jinja templating engine.
Prompting Primitives
Outlines uses Jinja2 for crafting complex prompts. This separation of prompt logic from the general program logic allows for clear and concise prompts. For instance, you can build a sentiment analysis prompt like this:
import outlines


examples = [
    ("The food was disgusting", "Negative"),
    ("We had a fantastic night", "Positive"),
    ("Recommended", "Positive"),
    ("The waiter was rude", "Negative")
]


@outlines.prompt
def labelling(to_label, examples):
    """You are a sentiment-labelling assistant.
    {% for example in examples %}
    {{ example[0] }} // {{ example[1] }}
    {% endfor %}
    {{ to_label }} //
    """


model = outlines.models.transformers("mistralai/Mistral-7B-v0.1")
prompt = labelling("Just awesome", examples)
answer = outlines.generate.text(model, max_tokens=100)(prompt)
Custom Jinja Filters for Function Integration
Outlines introduces custom Jinja filters that extract function names, descriptions, signatures, and source code. This feature is handy when integrating external functions into prompts:
from typing import Callable, List
import outlines


def google_search(query: str):
    """Google Search"""
    pass


@outlines.prompt
def my_commands(tools: List[Callable]):
    """AVAILABLE COMMANDS:
    {% for tool in tools %}
    TOOL
    {{ tool | name }}, {{ tool | description }}, args: {{ tool | signature }}
    {{ tool | source }}
    {% endfor %}
    """


prompt = my_commands([google_search])
Response Models
Outlines allows developers to define the expected response format, often in JSON, using Pydantic models. This approach streamlines the generation of structured responses:
from pydantic import BaseModel, Field
import outlines


class Joke(BaseModel):
    joke: str = Field(description="The joke")
    explanation: str = Field(description="The explanation of why the joke is funny")


@outlines.prompt
def joke_ppt(response_model):
    """Tell a joke and explain why the joke is funny.
    RESPONSE FORMAT:
    {{ response_model | schema }}
    """


joke_ppt(Joke)
You can find more practical examples by exploring the Outlines library documentation.
Conclusions
This article highlights the importance of practical, prompt engineering for getting the most out of large language models. It covers various techniques, from simple to complex, such as Zero-Shot, Few-Shot, Chain-of-Thought, and Retrieval Augmented Generation, each addressing different needs and uses for LLMs. Additionally, evolving tools like Guidance, LangChain, and Outlines show progress in this area, offering improved ways to interact with models for tasks like content creation and complex decision-making. Understanding and using these techniques and tools is vital for developers, researchers, and all enthusiasts as LLMs evolve, helping to create more intelligent, efficient, and user-friendly AI systems.
DRL Team ↗
AI R&D Center
Our team shares experiences and insights on how AI and ML change and shape new markets, optimize various industries and our lives.
Ivan Didur ↗
CTO @ DataRoot Labs
Ivan Didur is a co-founder and CTO of DataRoot Labs. As the head of technology, Ivan manages the entire tech team, designs projects architecture, and makes critical technology decisions. He has extensive hands-on experience in all core AI technologies, including Computer Vision, Natural Language Processing, and Deep Reinforcement Learning. He eagerly tries every new AI technology and method in DataRoot research lab and if it passes his high bar, it imminently gets into production on one of our cases. Additionally, Ivan actively mentors aspiring Data Scientists at the DataRoot University.