Large-scale search-query clustering
Summary
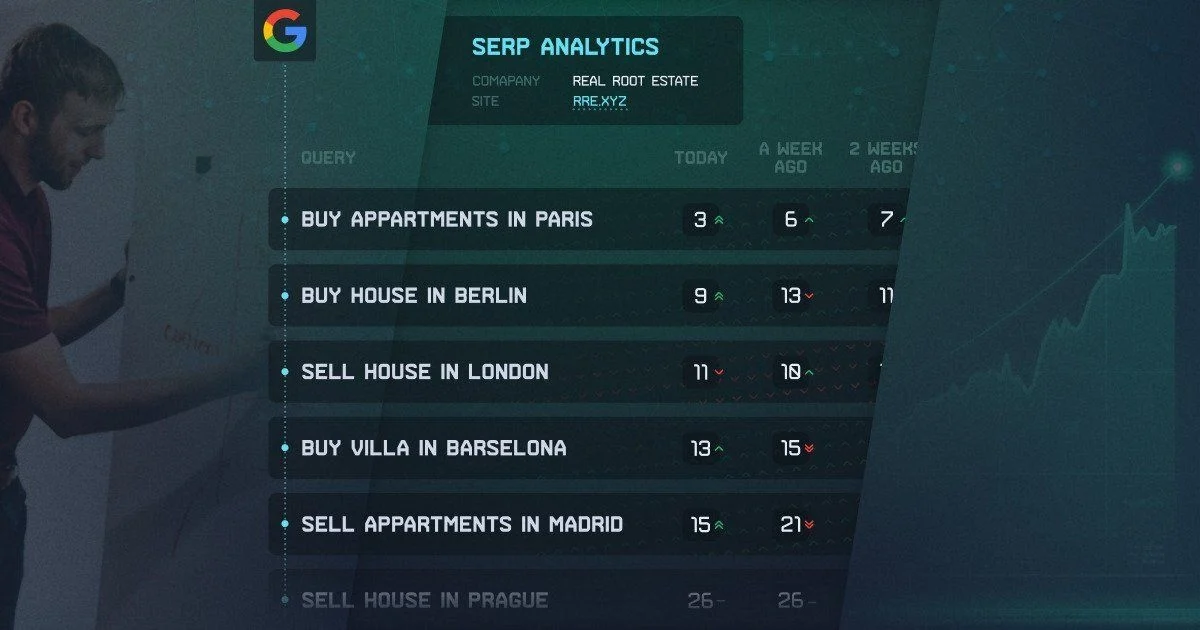
A data warehouse for SERP analytics.
The client needed to organise large query and search-result datasets into useful groups for analysis.
A distributed warehouse and clustering pipeline using Spark and a customised locality-sensitive hashing approach.
Tech Stack
- Akka
- Apache Spark
- Cassandra
- GlusterFS
- Kafka
- PostgreSQL
- Python
- Scala
- TensorFlow
Project workstreams
- 01
2 Weeks
Data Gathering Parser
Data Engineer - 02
1 Week
Solution Architecture Design
Solution Architect - 03
1 Week
Feature Extraction Pipeline Development
Deep Learning Engineer,Deep Learning Researcher - 04
1 Week
Development of Customised LSH
Deep Learning Researcher,Deep Learning Engineer - 05
1 Week
Clustering Performance Optimization
Deep Learning Engineer,Data Engineer - 06
2 Weeks
Data Warehouse Configuration
Data Engineer - 07
6 Weeks
Web Platform Development
Backend Developer,Frontend Developer - 08
2 Weeks
Integration & Deployment
Backend Developer,Dev Ops
Tech Challenge
- Implementation required removal of the laborious manual tasks from the SEO team, allowing the client to considerably improve quality and revenues of the services.
- It was important that the entire range of analytics, from days to years, is in full disposal of the SEO specialist to adjust the parameters and predict the outcome.
- Parsing of Google Search Console of the websites and then parse google for search queries results taken from GSC.
- Clustering query-results matrix by links where the size of the matrix could be tens of millions squared.
Solution
- Queries are prepared by a natural-language-processing pipeline to support recurring search-position analysis.
- This algorithm considers structure and content of the target site pages and builds huge amounts of different textual queries to get the whole picture of the site’s performance.
- Those queries are performed and stored inside the database on a daily basis for whole range of sites. Each site is then analyzed against the competition, using the tool we have built.
- Different ranges of analytics on day-to-years scale are accessible to the SEO specialist for further iterations.
- A customised Apache Spark locality-sensitive hashing pipeline groups queries with similar search results. Approximate matching reduces the need for exhaustive pairwise comparisons.
Outcome
A distributed warehouse and query-clustering service for search analytics.
The service supports recurring analysis and grouping of search-query data without manually preparing every query set.
Published